SpacemiT AI LabSpacemiT AI Lab is a web-based AI evaluation platform. A cloud K3 instance can be requested from a browser to evaluate model inference results and real performance data on a SpacemiT K3 AI CPU — zero configuration, instant access, and no hardware required.
K3 devices also include a built-in AI Lab desktop application for downloading models and running them locally.
Key Capabilities
- Cloud hardware access: Request a cloud K3 instance and run inference directly on real hardware from a browser, with live results and performance metrics.
- Vision models: Object detection, image segmentation, pose estimation, face recognition, and image classification.
- Large language model chat: Intelligent Q&A and text generation with streaming output.
- Speech recognition (ASR): Audio-to-text transcription with real-time microphone input.
- Speech synthesis (TTS): Text-to-speech playback.
- Voice activity detection (VAD): Speech segment detection and boundary splitting.
- Model performance dashboard: View per-model performance metrics measured on real K3 hardware (FPS / RTF / token/s).
Platform Support
Platform & OS
Supported
K1 Buildroot
 No
K1 OpenHarmony
No
K1 Bianbu LXQT/GNOME
No
K3 Buildroot
No
K3 OpenHarmony
No
K3 Bianbu LXQT/GNOME
 Yes
ArchitectureSystem Architecture Diagram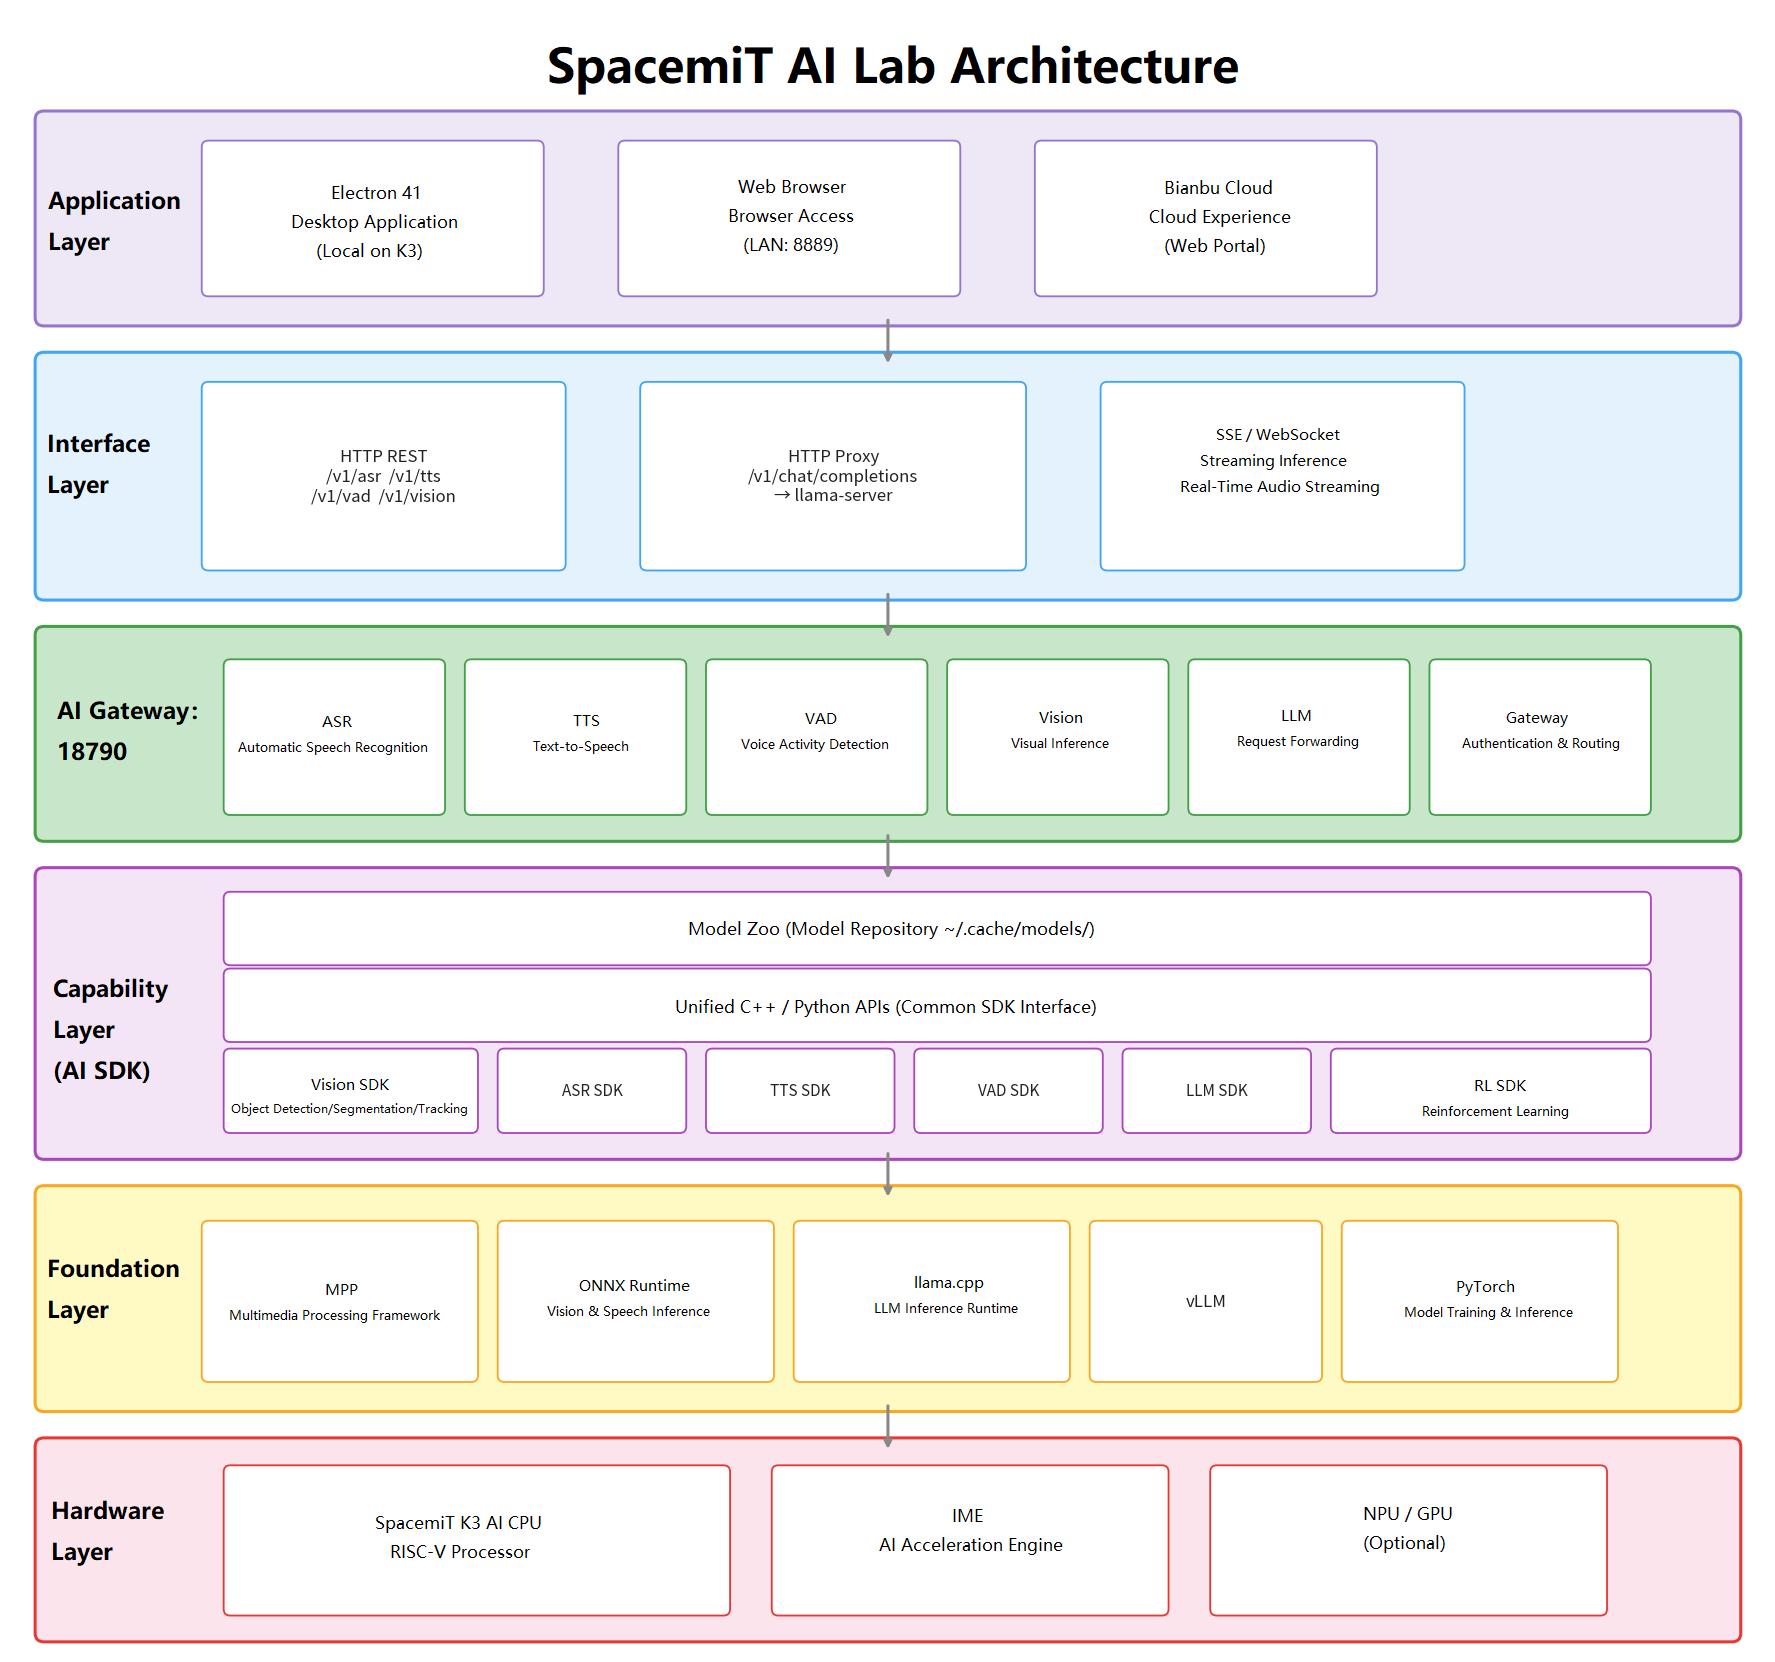
Application Stack
- Desktop framework: Electron 41 (RISC-V optimized build, K3 local app)
- Frontend: Vanilla JavaScript + HTML5 + CSS3
- Backend: SpacemiT AI Gateway (port 18790)
- Model inference: ONNX Runtime (vision/speech models) + llama.cpp (LLM, SpacemiT-accelerated build)
Dependent Services
- AI Gateway: Unified inference gateway that exposes ASR / TTS / VAD / Vision / LLM domain APIs over HTTP/WebSocket (/v1/asr, /v1/tts, /v1/vad, /v1/vision, /v1/chat/completions).
- llama-server: Standalone LLM data-plane service; inference requests are proxied through AI Gateway (port 8080).
- Model data source: Latest model metadata and performance data are fetched from the SpacemiT Model Zoo.
Workflows
- Cloud experience
Bianbu Cloud → Official website entry → AI Lab home page → Run online inference → View live performance data
- Local experience
Launch the AI Lab desktop app → Local app page → Download model → Try Now → Run inference → View live performance data
- LAN sharing
Launch app → Copy share link → Open link in another device’s browser
Installation (K3 Local App)
System Requirements
- OS: Bianbu 4.0 rc4 or later, LXQT or GNOME desktop
- Hardware: SpacemiT K3 RISC-V device
- Memory: 8 GB or more recommended
- Storage: At least 10 GB free space (for model downloads)
Installation
sudo apt update
sudo apt install spacemit-ailab spacemit-ai-gateway
The installer automatically configures the required systemd services.
Verify the Installation
# Check AI Gateway service status
systemctl status spacemit-ai-gateway

# Check the service endpoint
curl -s localhost:18790/healthz
Quick Start
1) Cloud Experience (Recommended)No hardware required. Access the cloud platform directly:
-
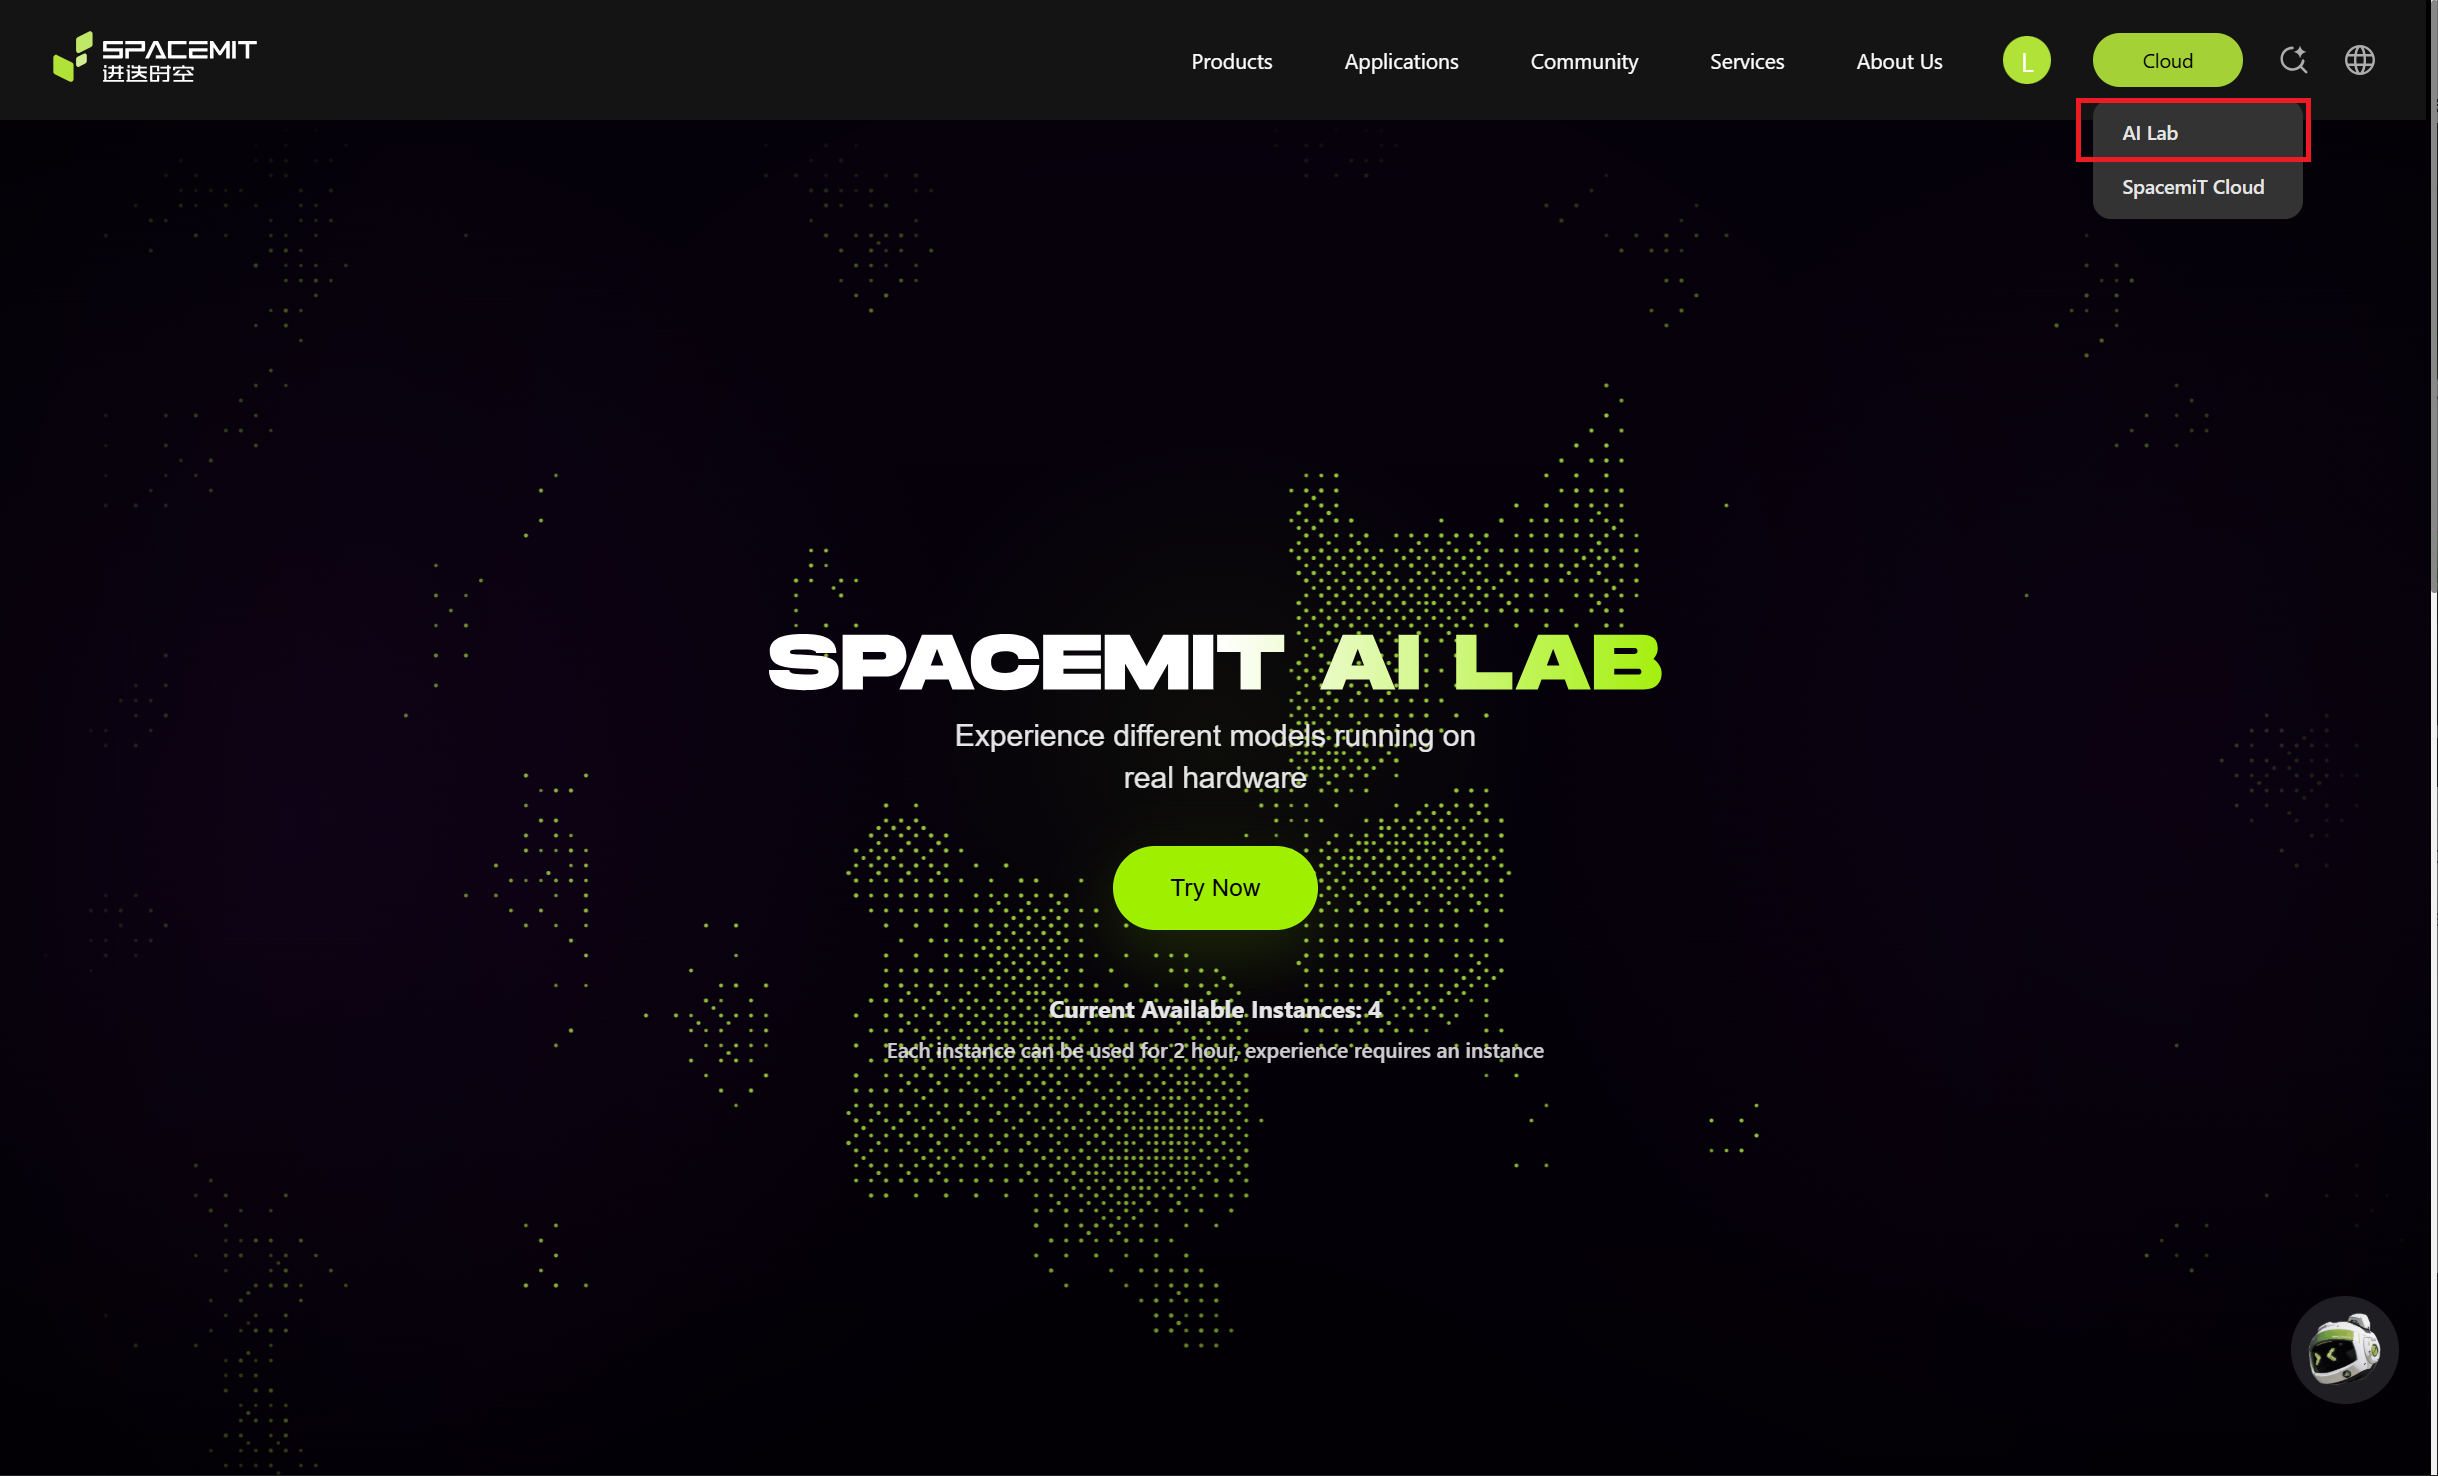
Open spacemit.com, click Cloud, select AI Lab, and navigate to the SpacemiT AI Lab cloud homepage.
-
Click Try Now and wait for the system to allocate a cloud K3 instance (typically under 3 seconds).
-
Once the instance is ready, the browser is automatically redirected to the Model Center, where models can be run immediately.
Note: Each session has a maximum duration of 2 hours. The instance is automatically reclaimed when the session times out or the page is closed.
2) K3 Local AppSearch for AI Lab in the system application menu, then launch it.
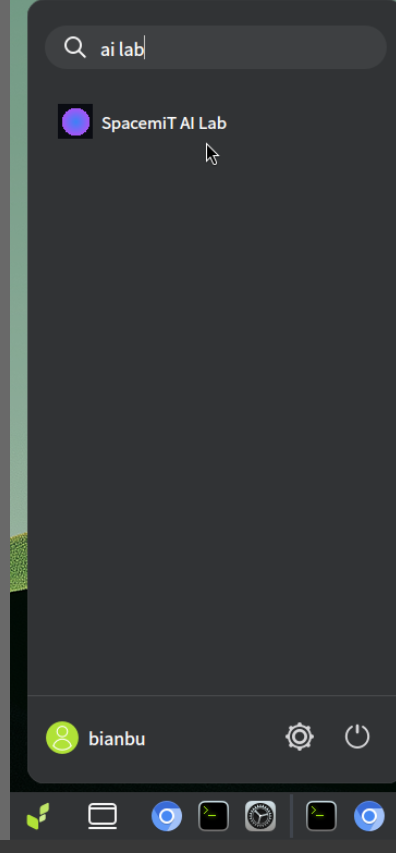
Tip: Right-click the app icon and select Add to Desktop, then mark it as trusted for quick access next time.
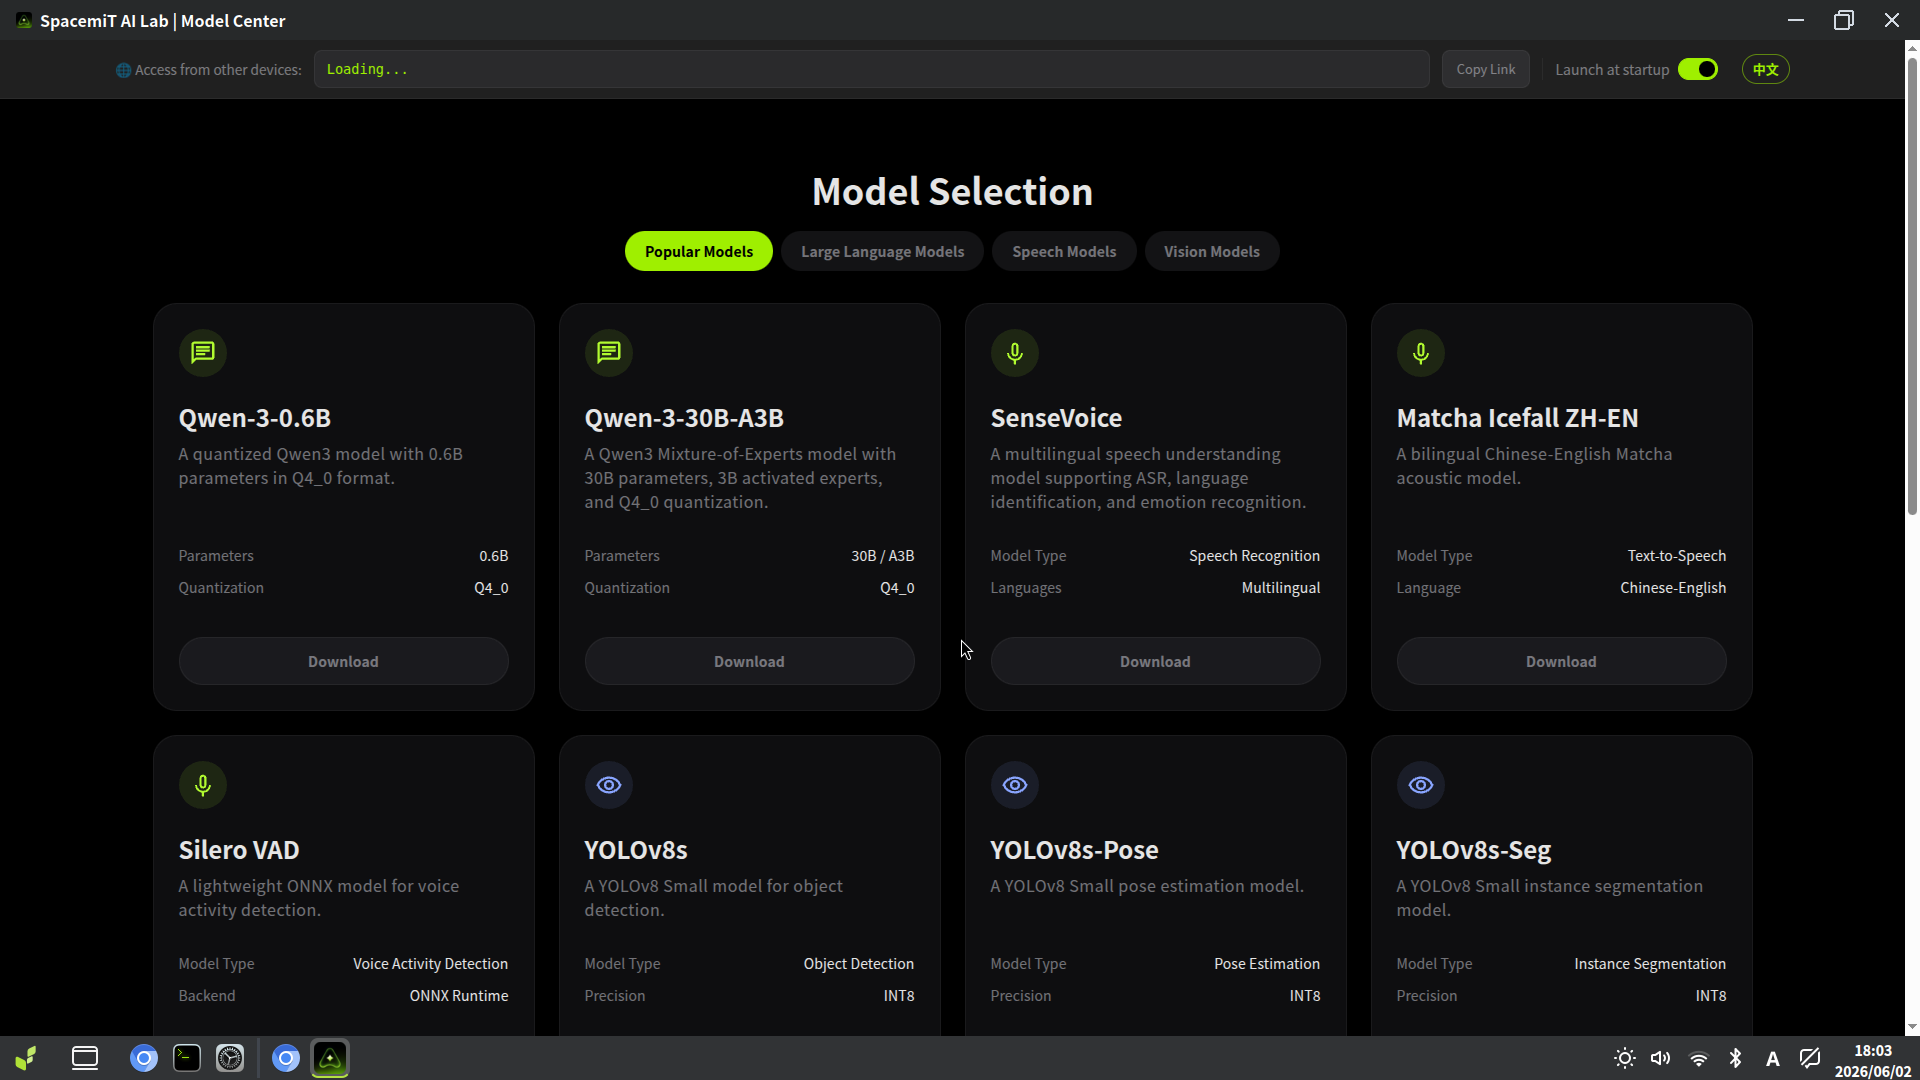
3) Interface OverviewAfter launch, the Model Center home page is displayed. It includes:
- Top navigation bar: LAN share link and copy button, auto-start on boot toggle, language switcher.
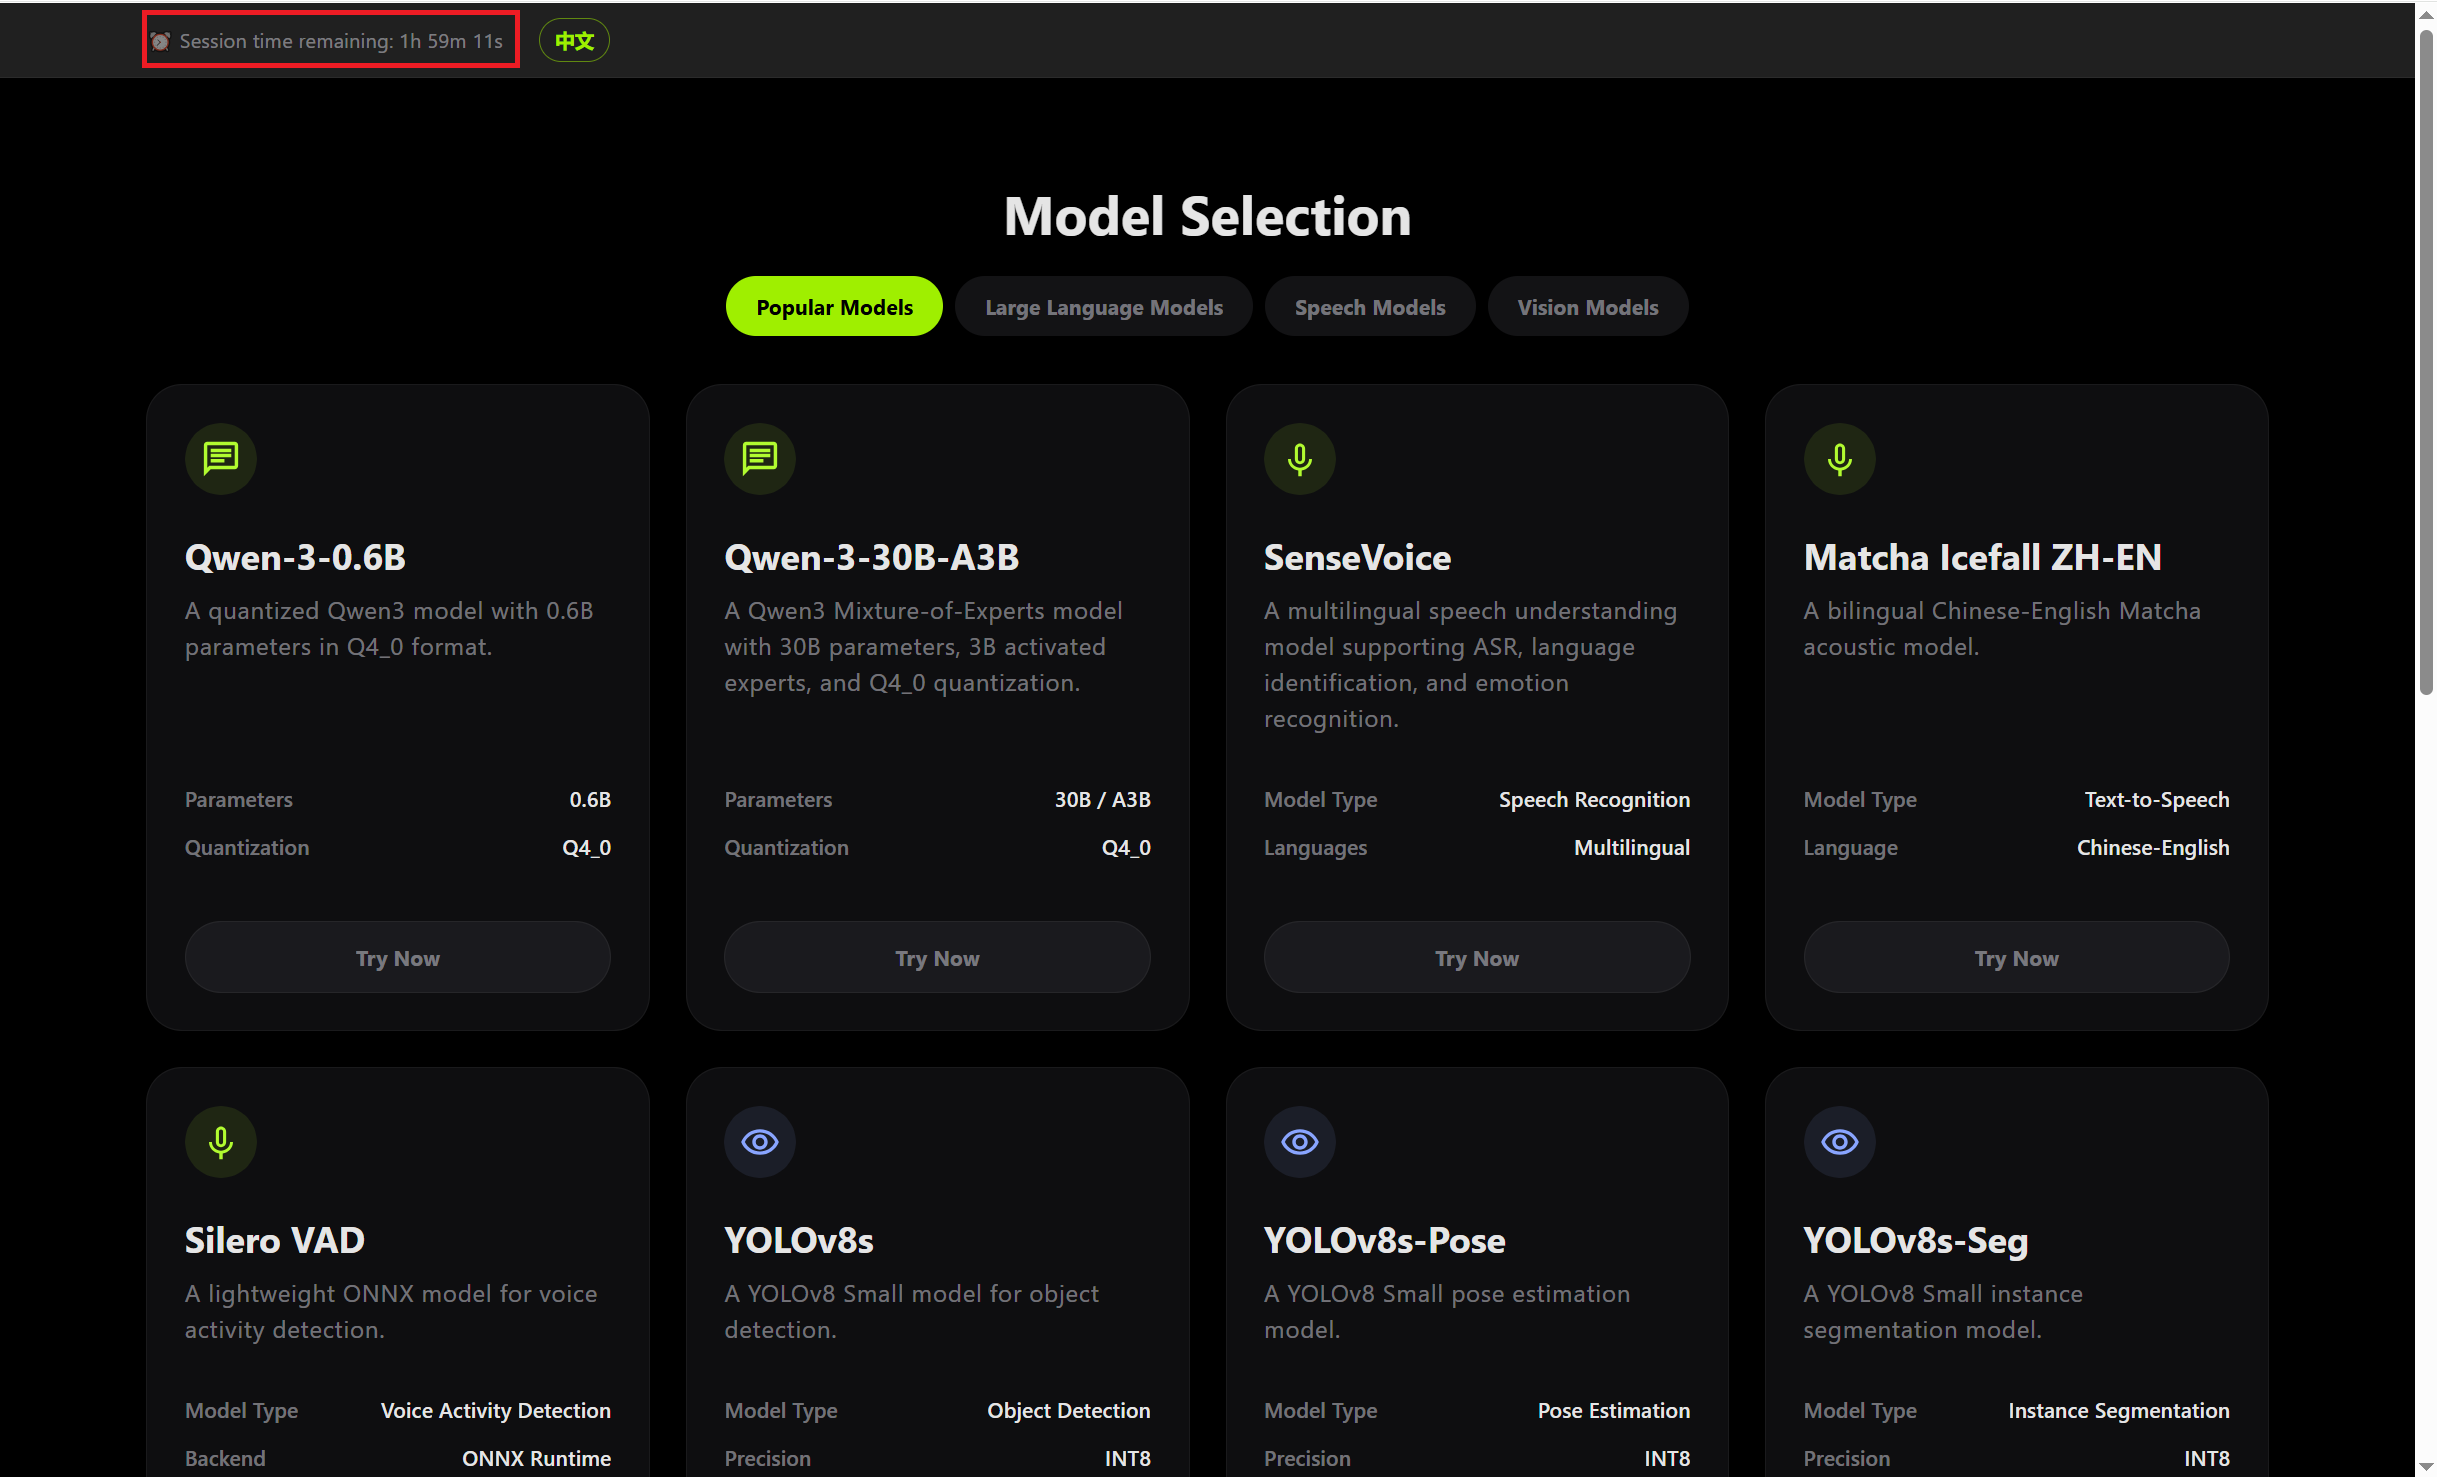
- Instance status bar: Displays remaining session time during cloud use.
- Model category tabs: Popular, Vision, LLM, Speech.
- Model card grid: Shows all available AI models with download and trial status.
- Performance dashboard: Per-model performance metrics on real K3 hardware.
Features
Cloud Instance Management
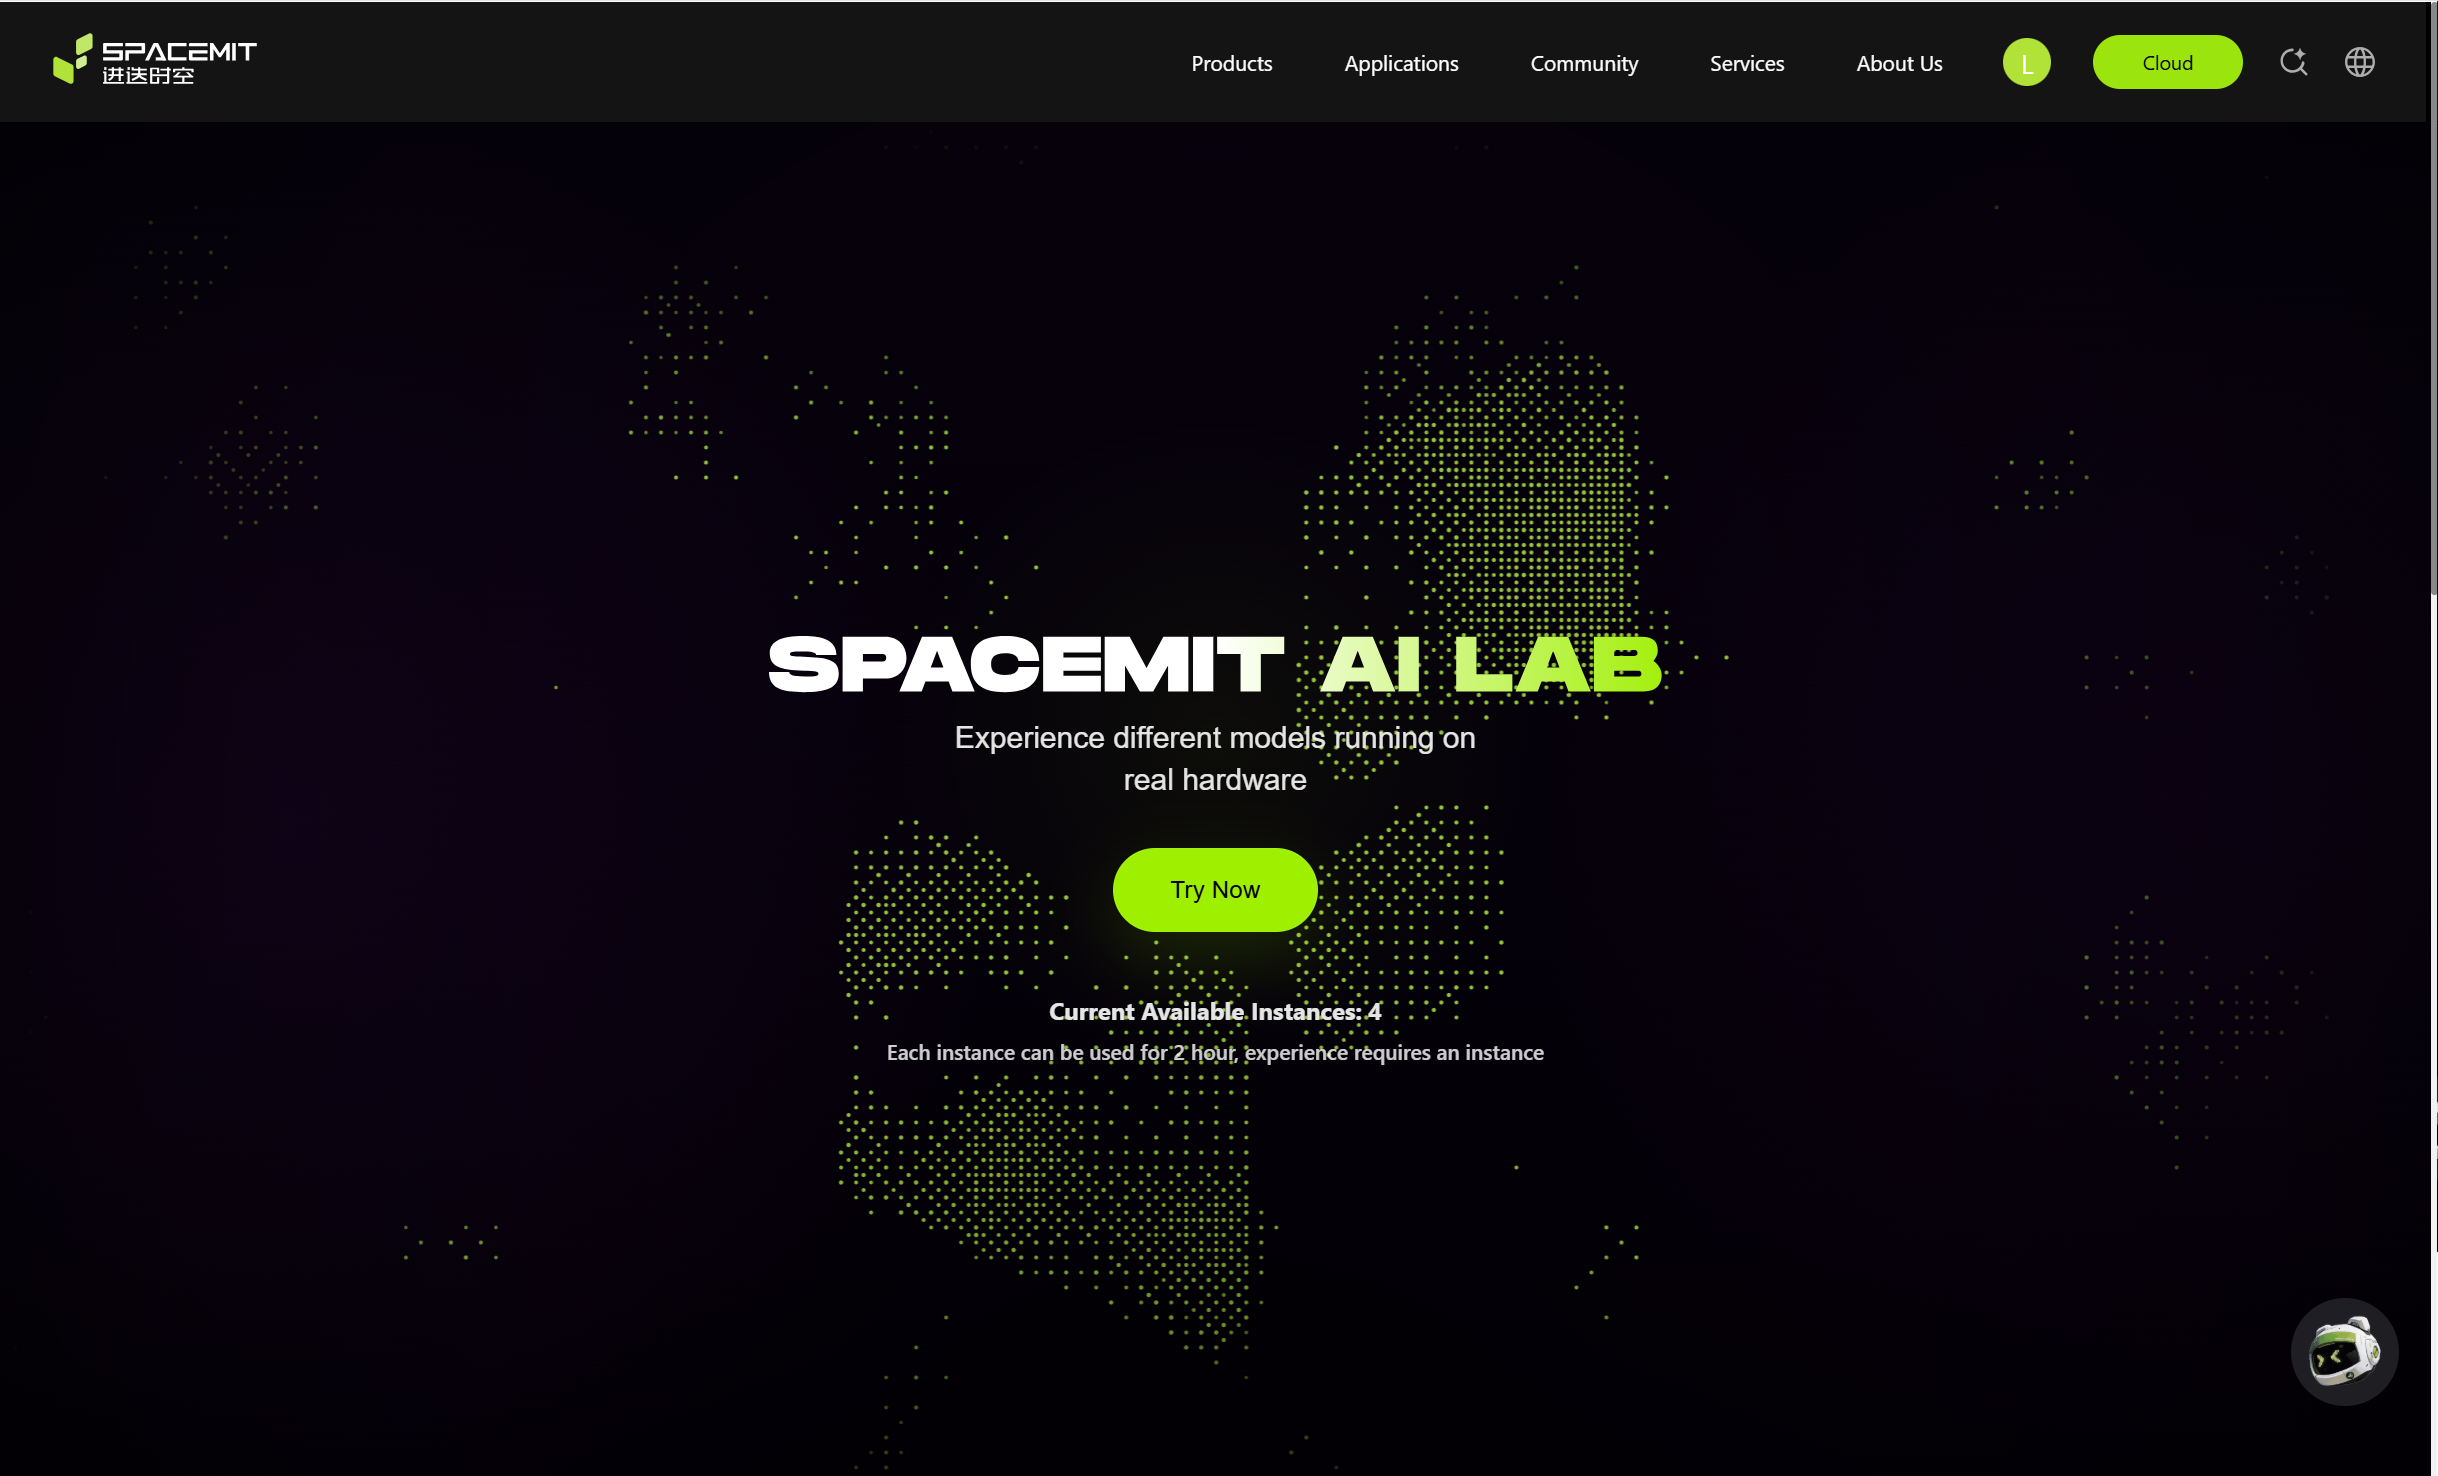
1) Requesting an InstanceOn the cloud platform home page, check the number of available instances, then click Try Now to obtain a dedicated K3 instance.
2) Session TimeAfter entering the Model Center, the top status bar shows the remaining session time (up to 2 hours). A warning appears before the session expires.
3) Releasing an Instance
- Automatic release: The instance is reclaimed automatically after 2 hours or when the Model Center page is closed.
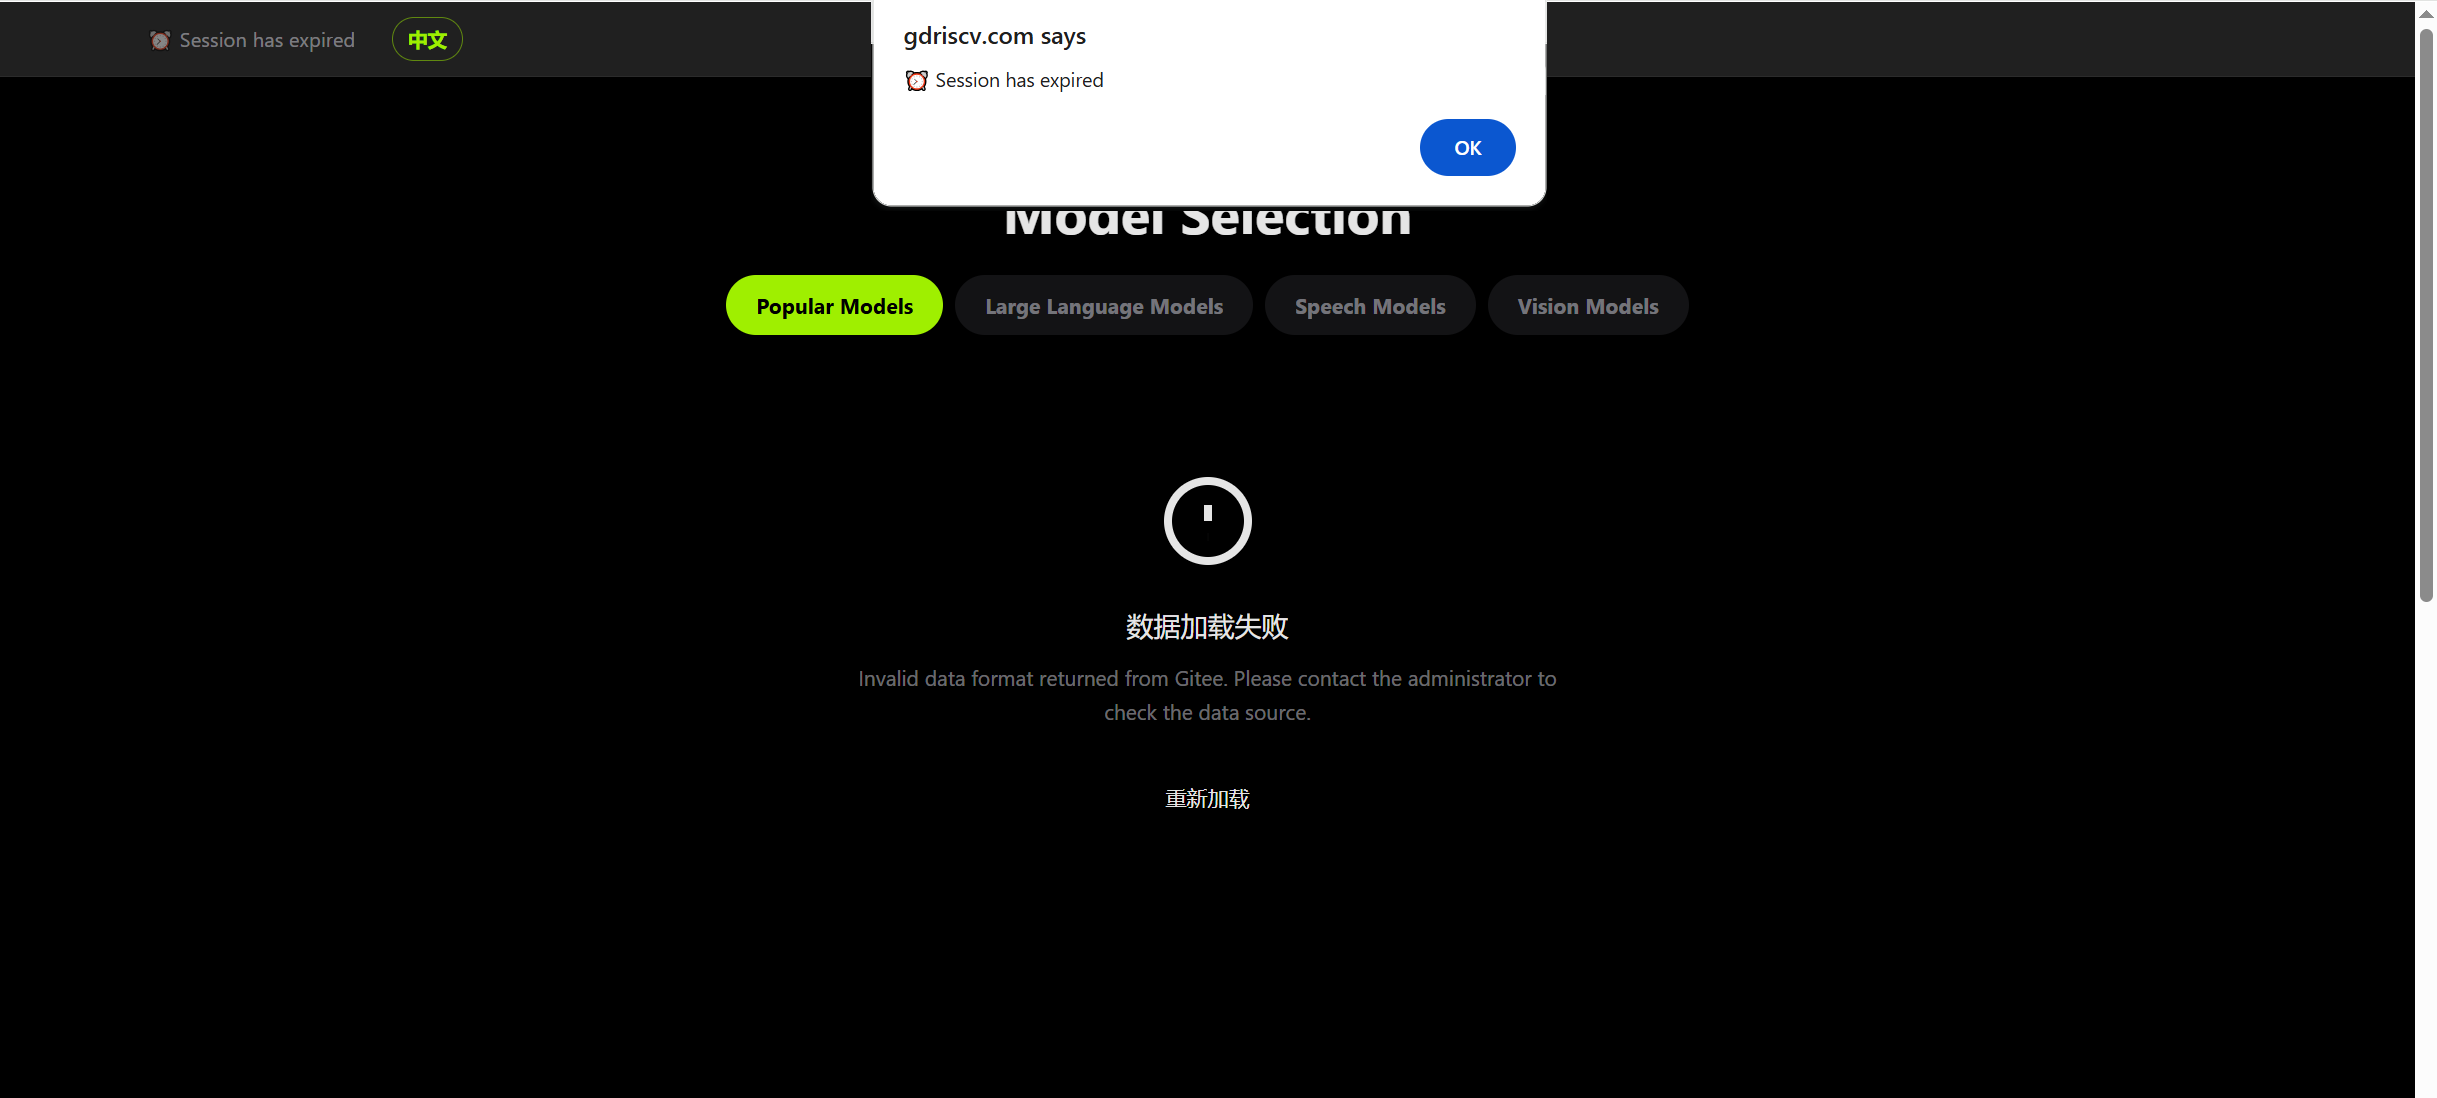
Privacy notice: When an instance is released, the application automatically clears all user data generated during the session, including LLM conversation history, uploaded images, recordings, and audio temp files. All data is processed in memory only and is never persisted to disk.
Model Center
1) Browsing by CategoryClick the category tabs at the top of the page to filter models:
- Popular: Most frequently used models.
- Vision: Object detection, image segmentation, pose estimation, image classification, and more.
- LLM: Conversational AI, text generation.
- Speech: ASR transcription, TTS synthesis, VAD detection.
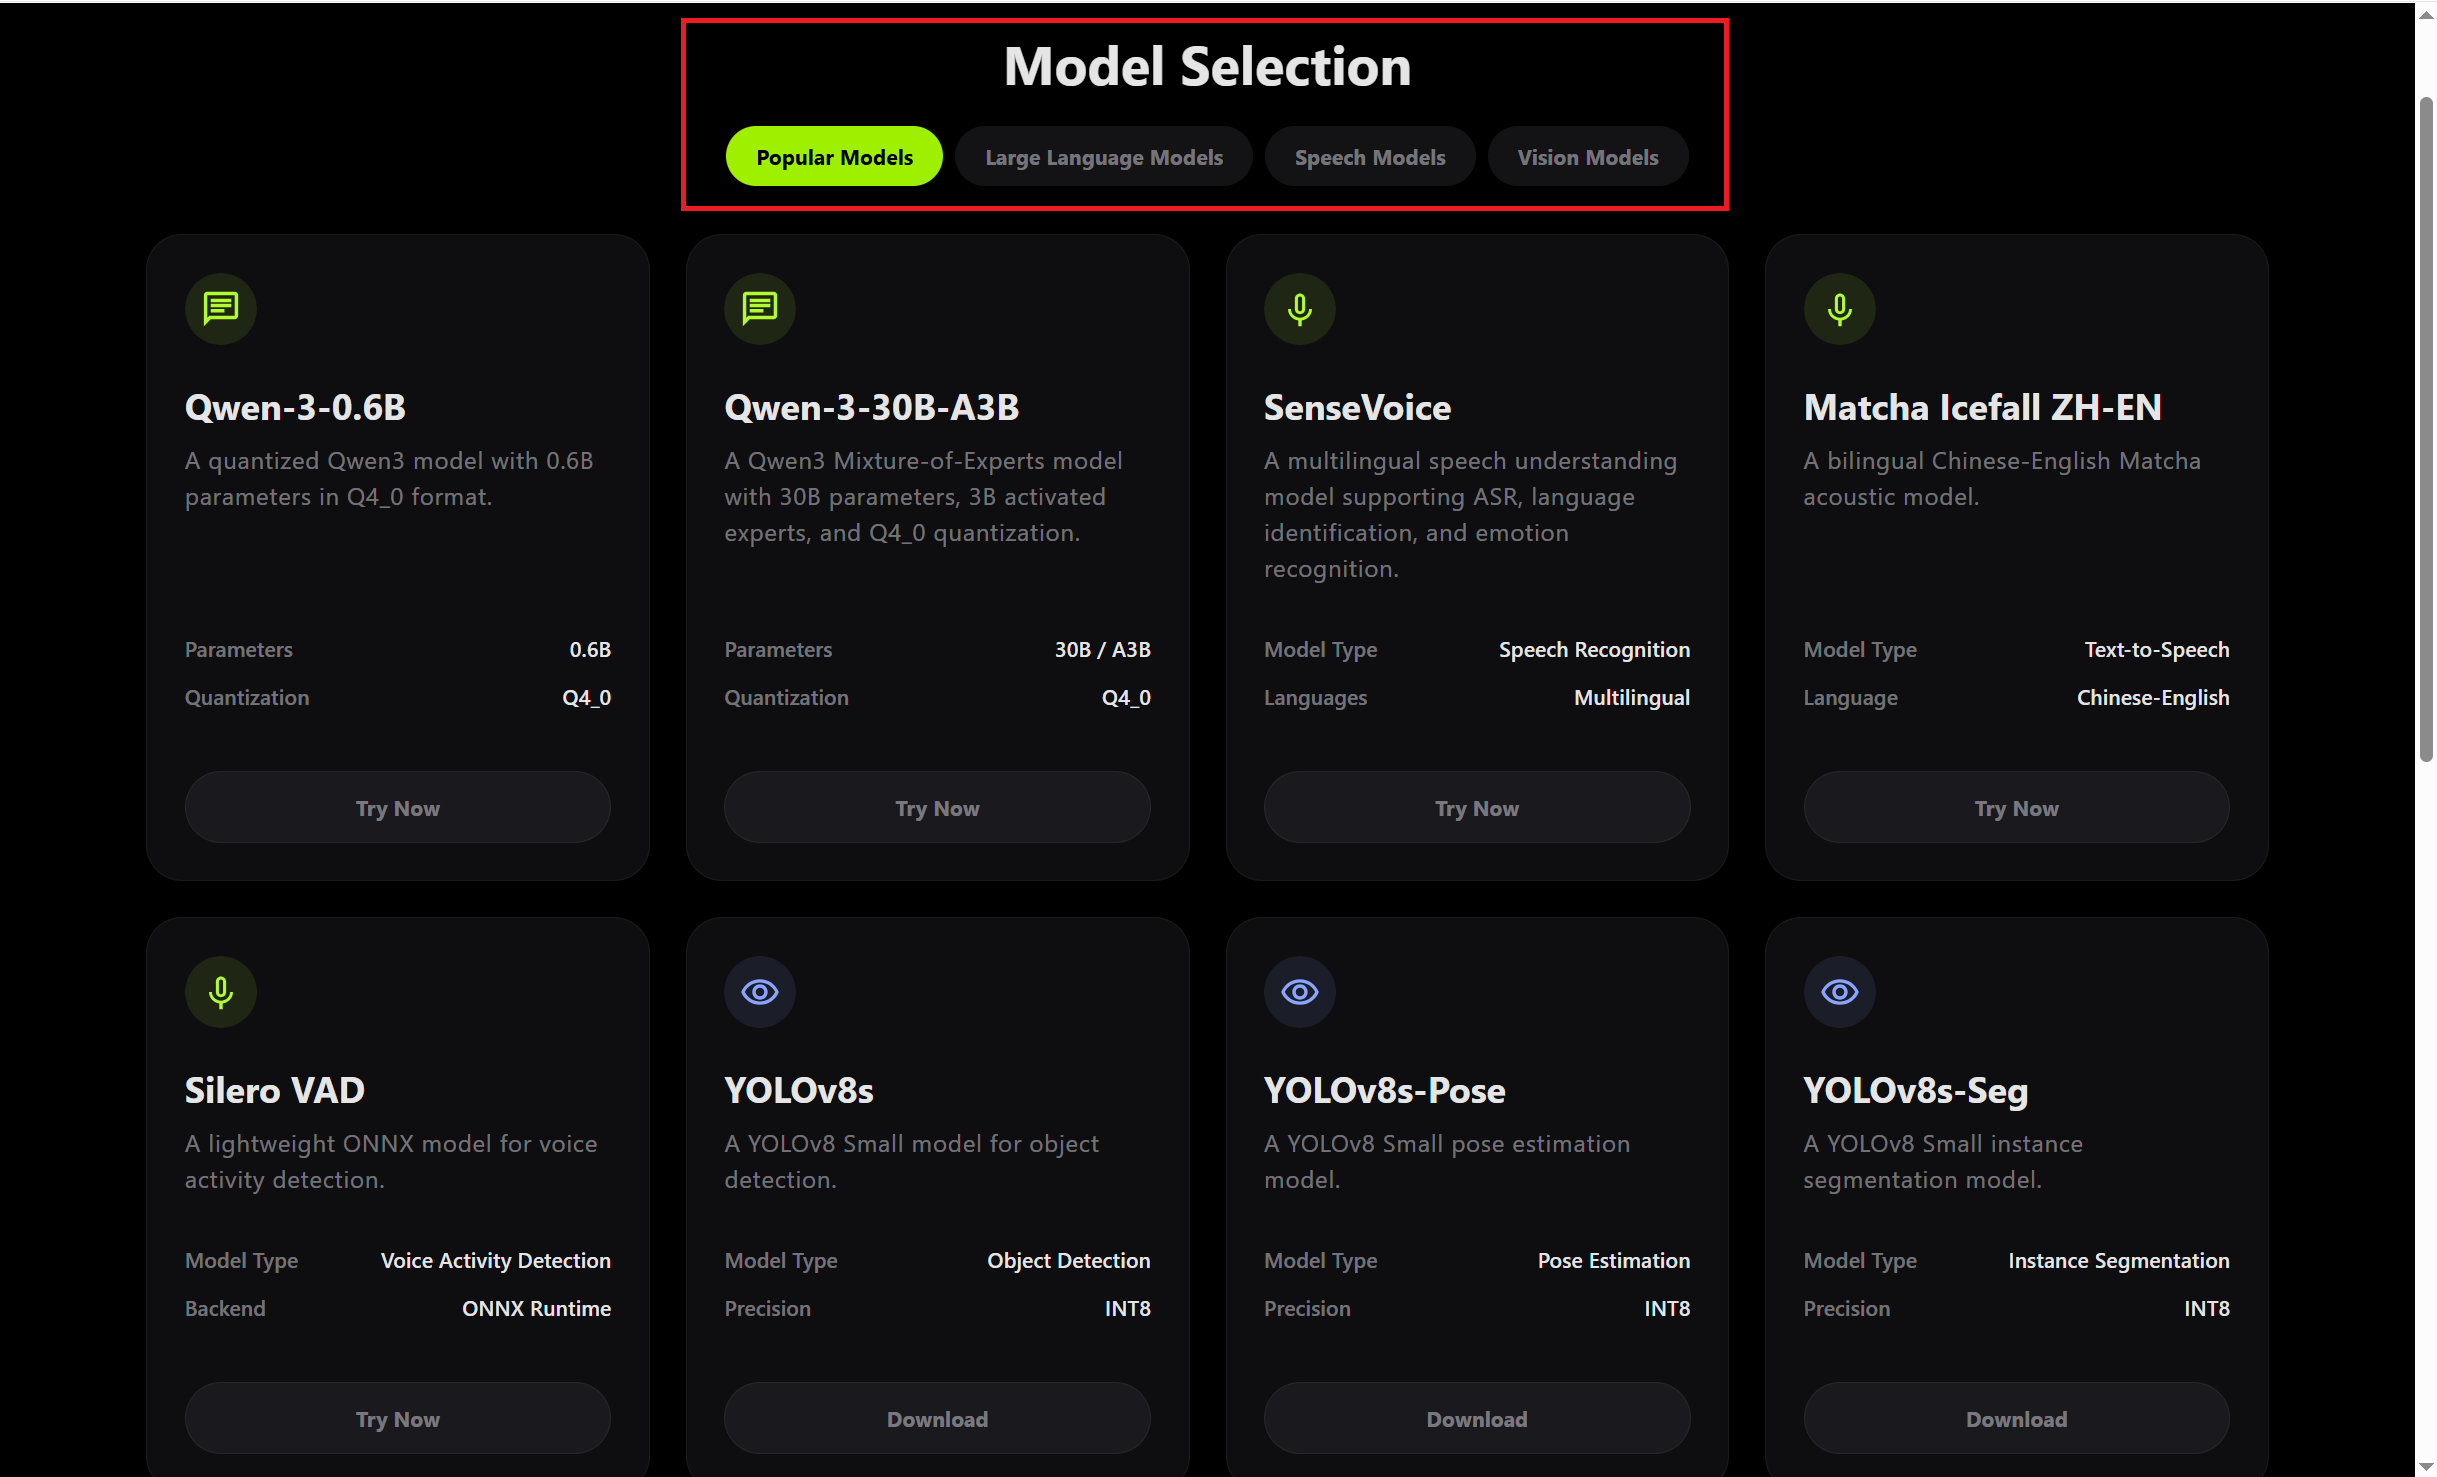
2) Model Card DetailsEach model card shows:
- Model name and task type
- Input specification (dimensions / format)
- Deployment precision (INT8, FP16, etc.)
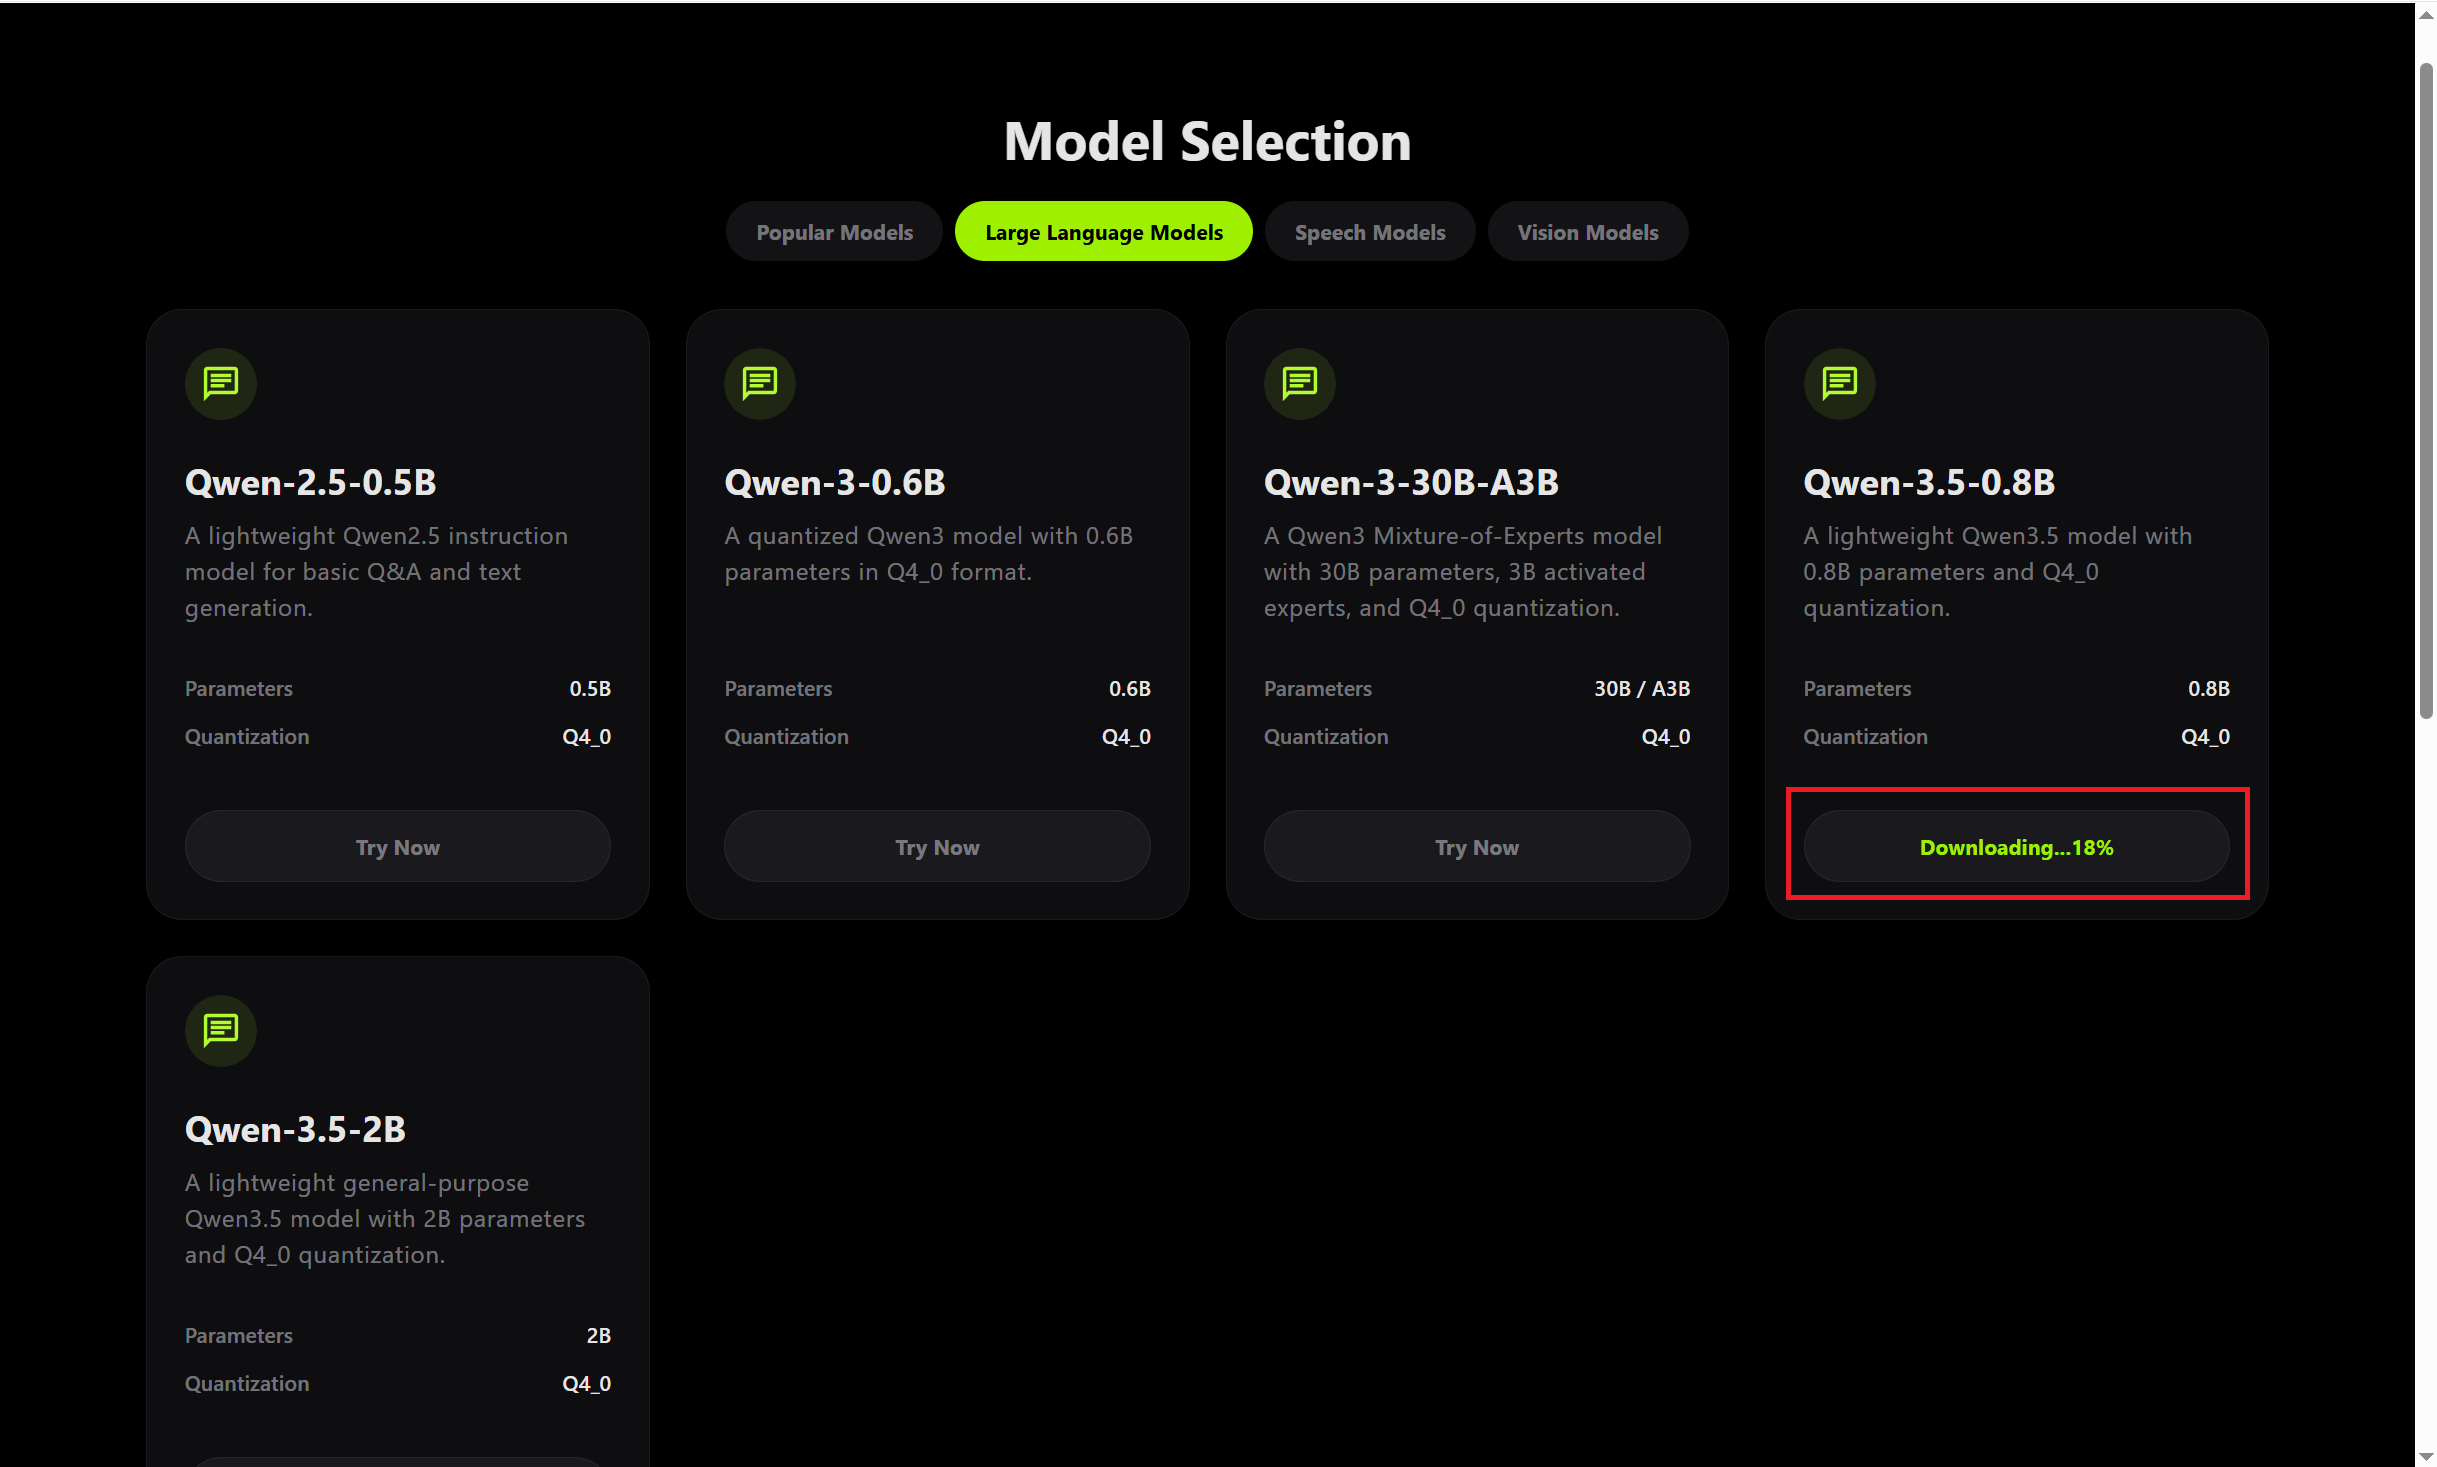
- Download state: Not downloaded (shows the Download Model button) / Downloading (shows progress) / Downloaded (shows the Try Now button)
Downloading Models
- Click Download Model on the model card to start the download.
- All models are stored under ~/.cache/models/, organized by category.
Vision Models
- Find a vision model in the list (e.g., YOLOv8n, YOLOv11s) and click Try Now.
- Select a sample image from the left sidebar, or click Upload Image to use a local file.
- For object detection models, adjust the Confidence (default 0.35) and IoU threshold (default 0.45) as needed.
- After inference, view the annotated result (bounding boxes / keypoints / segmentation masks) and the performance metrics.
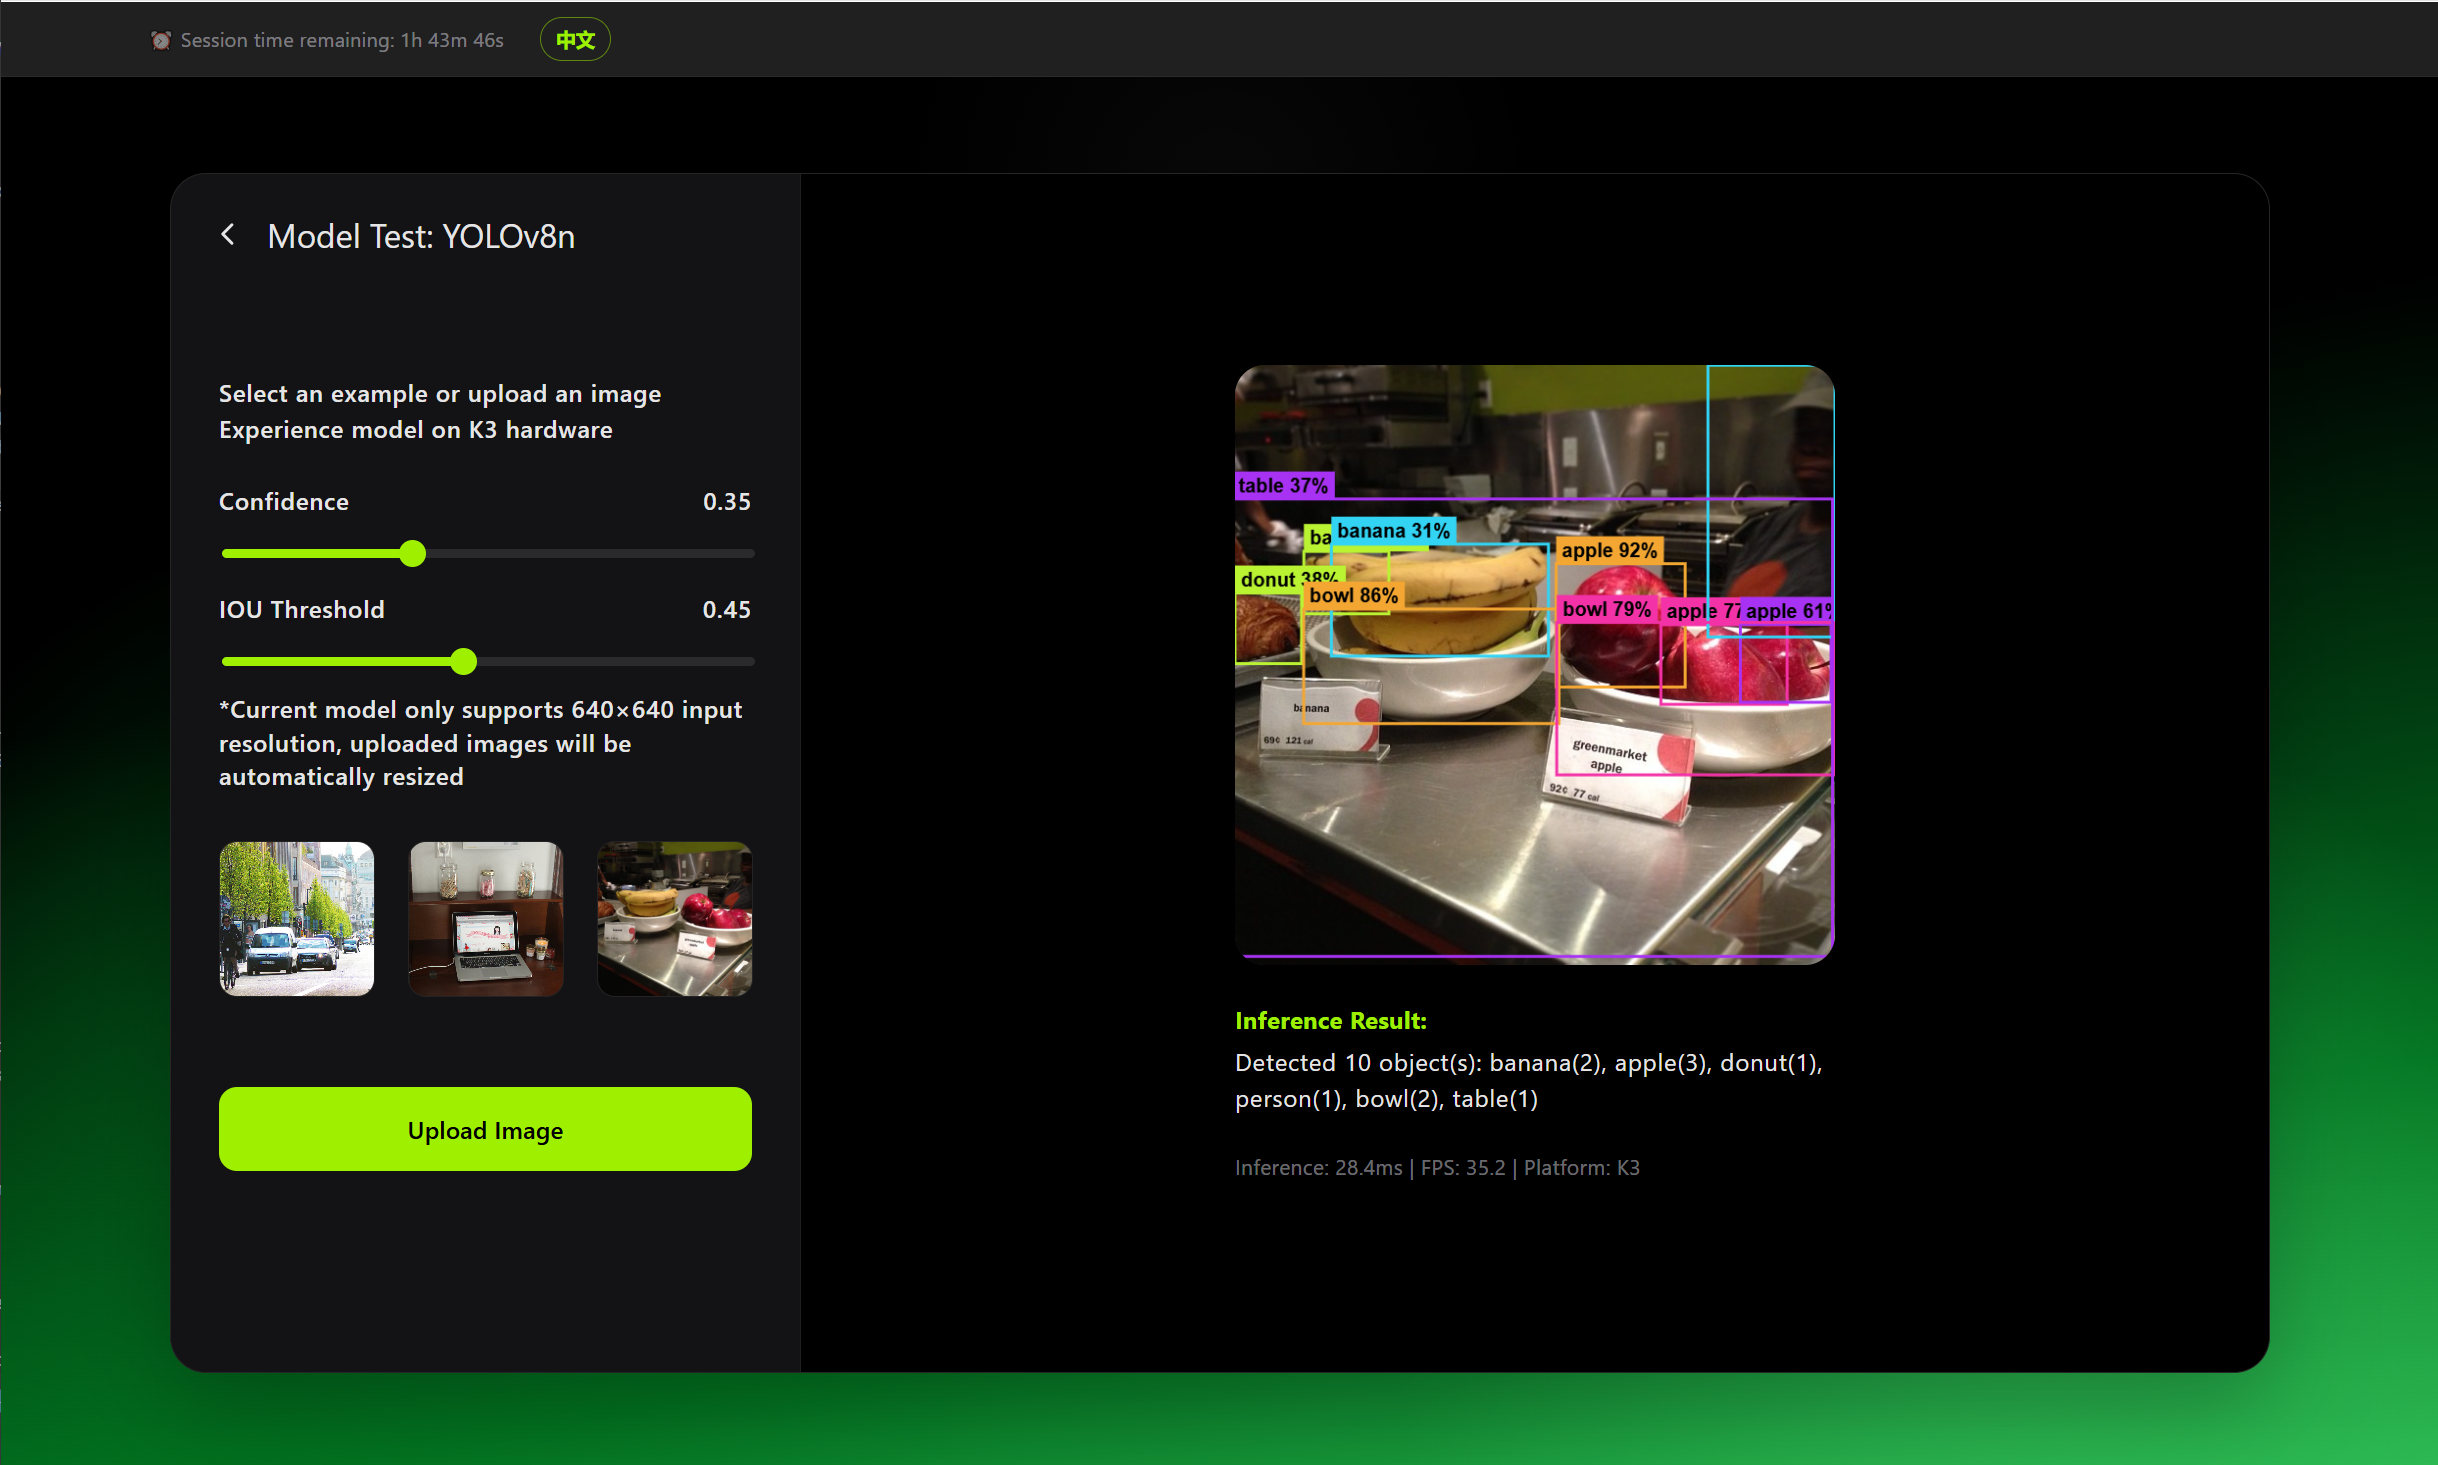
Supported vision tasks:
Task
Representative models
Object detection
YOLOv8n/s/m, YOLOv11n/s/m, YOLOv5-Gesture, YOLOv5n-Face
Image segmentation
YOLOv8n/s/m-seg series
Pose estimation
YOLOv8n/s/m-pose series
Face recognition
ArcFace-MobileFaceNet
Image classification
ResNet50
Large Language Model Chat
- Find an LLM (e.g., Qwen-3-0.6B) and click Try Now.
- Type a question in the input box at the bottom. Document links can also be attached. Press Enter or click the send icon.
- The model streams its response back; multi-turn conversation is supported.
- Click the copy button next to any message to copy the response.
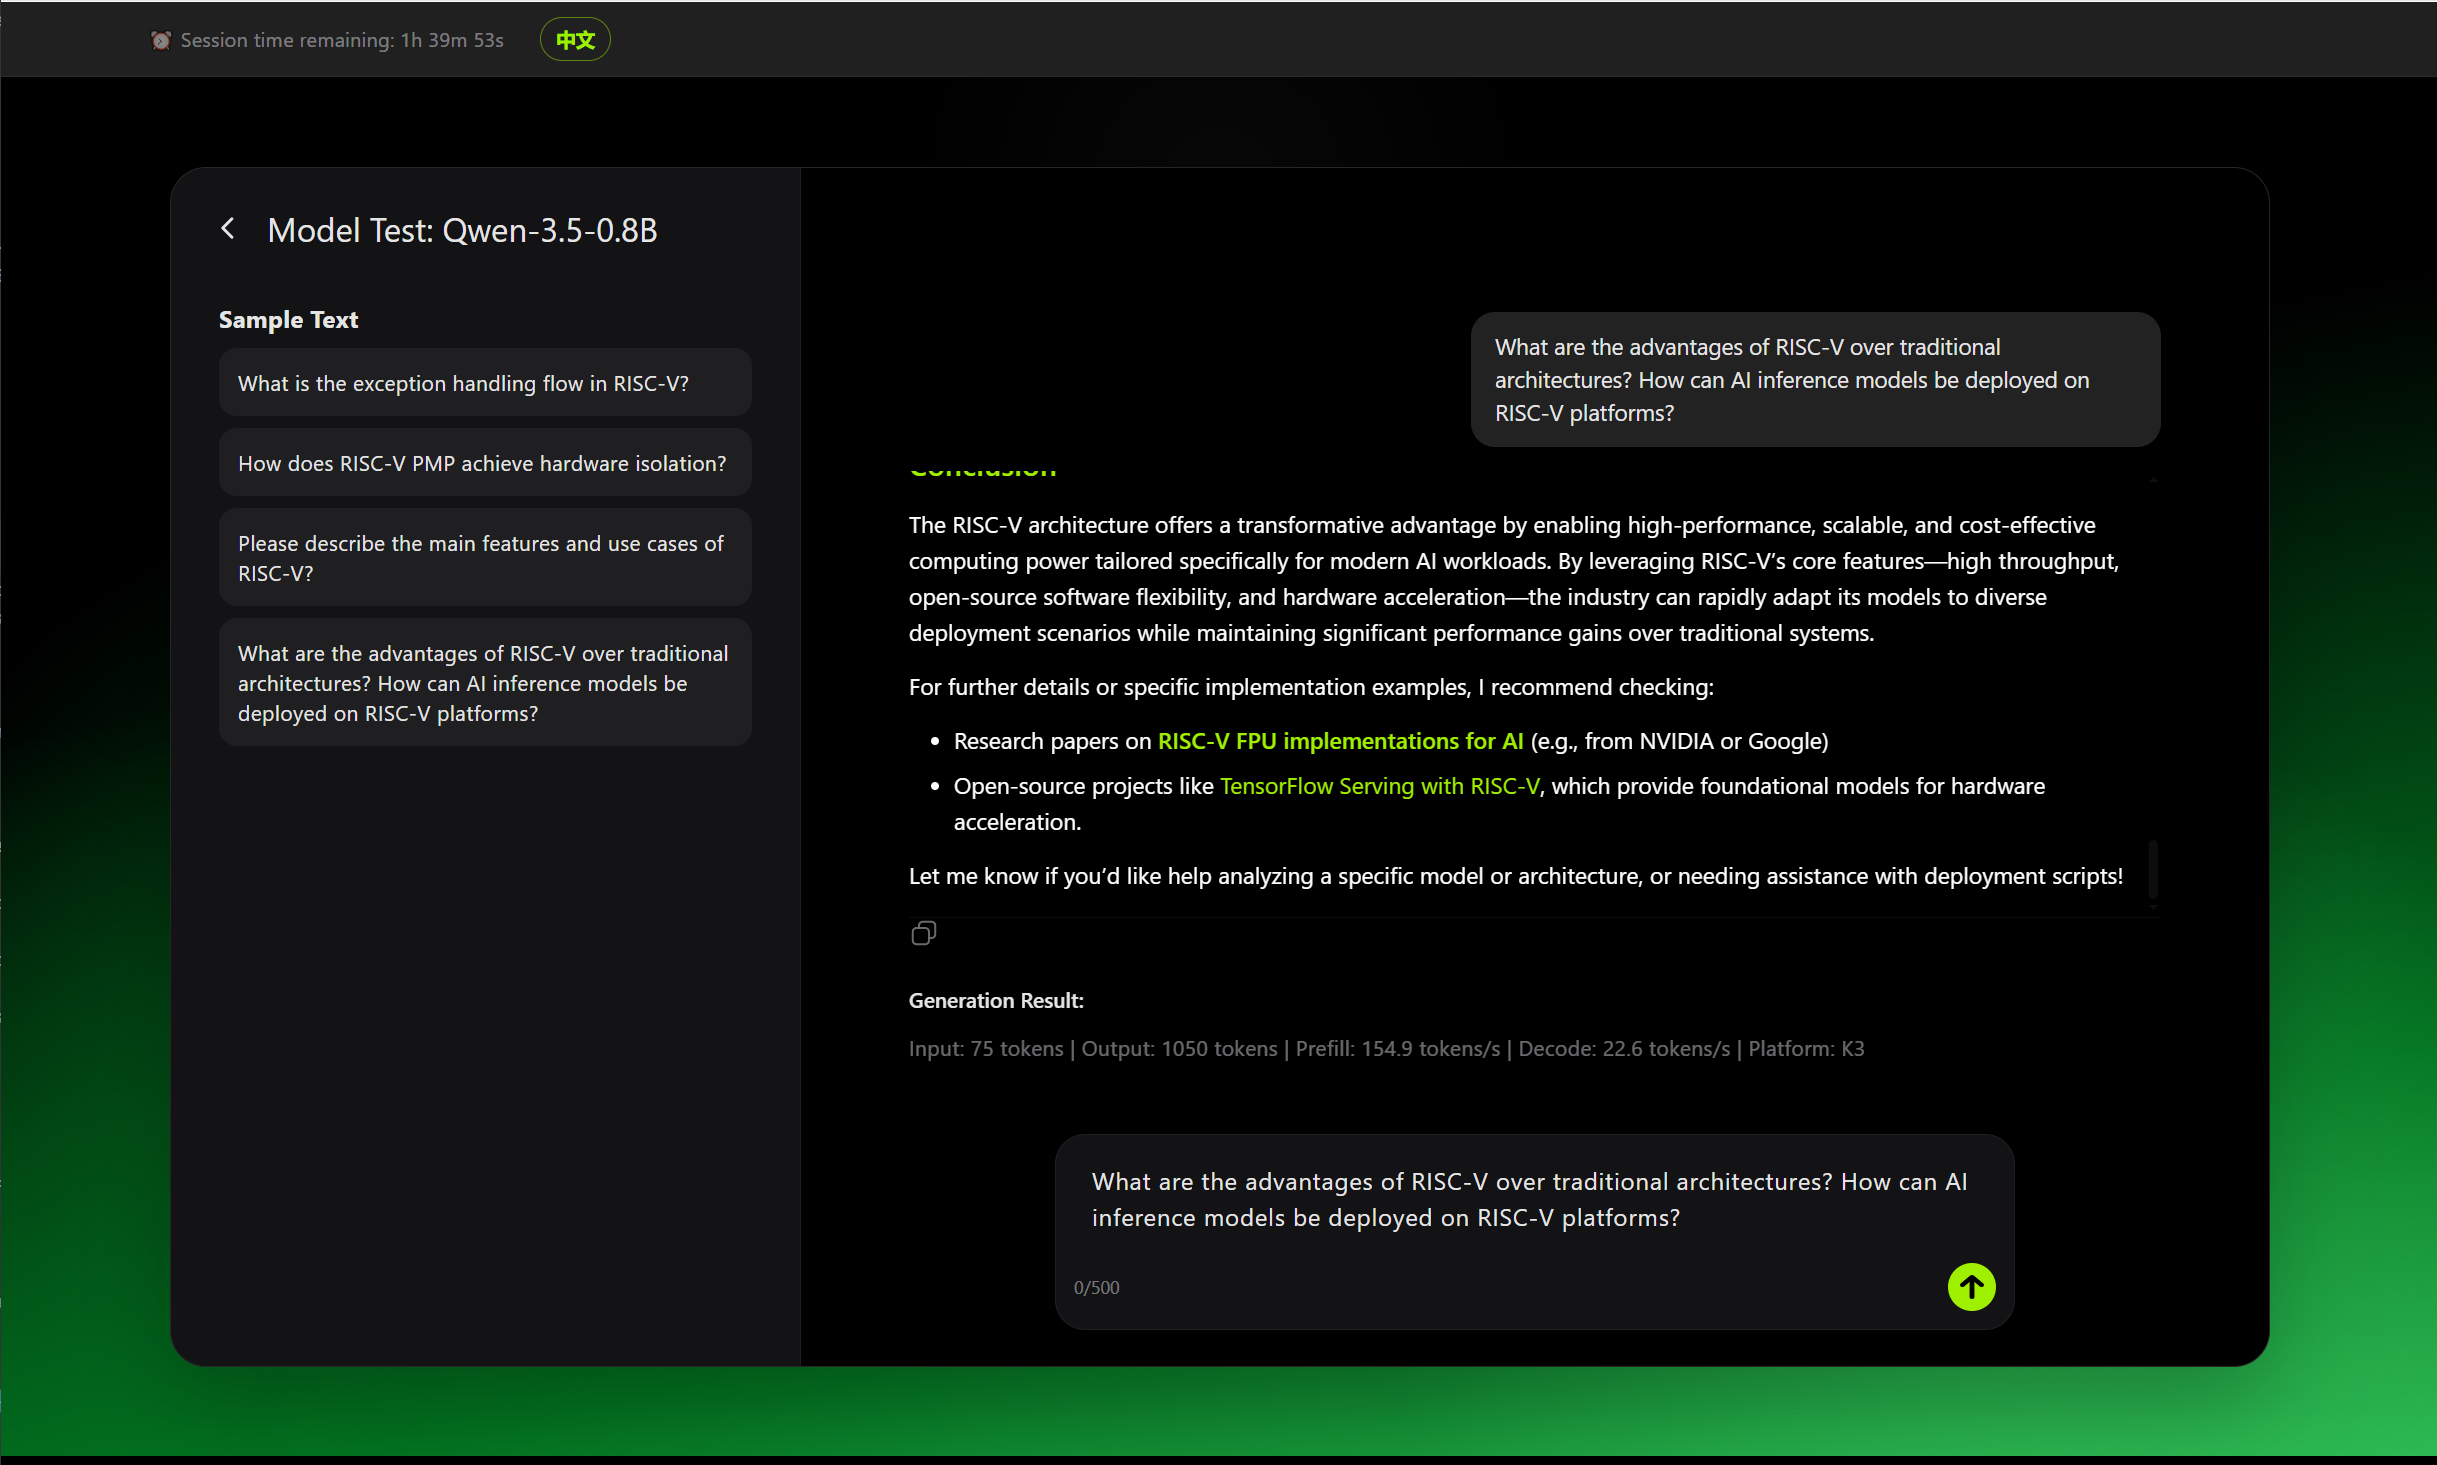
Supported LLM models: Qwen2.5, Qwen3, Qwen3.5 series, and more.
Speech Recognition (ASR)
-
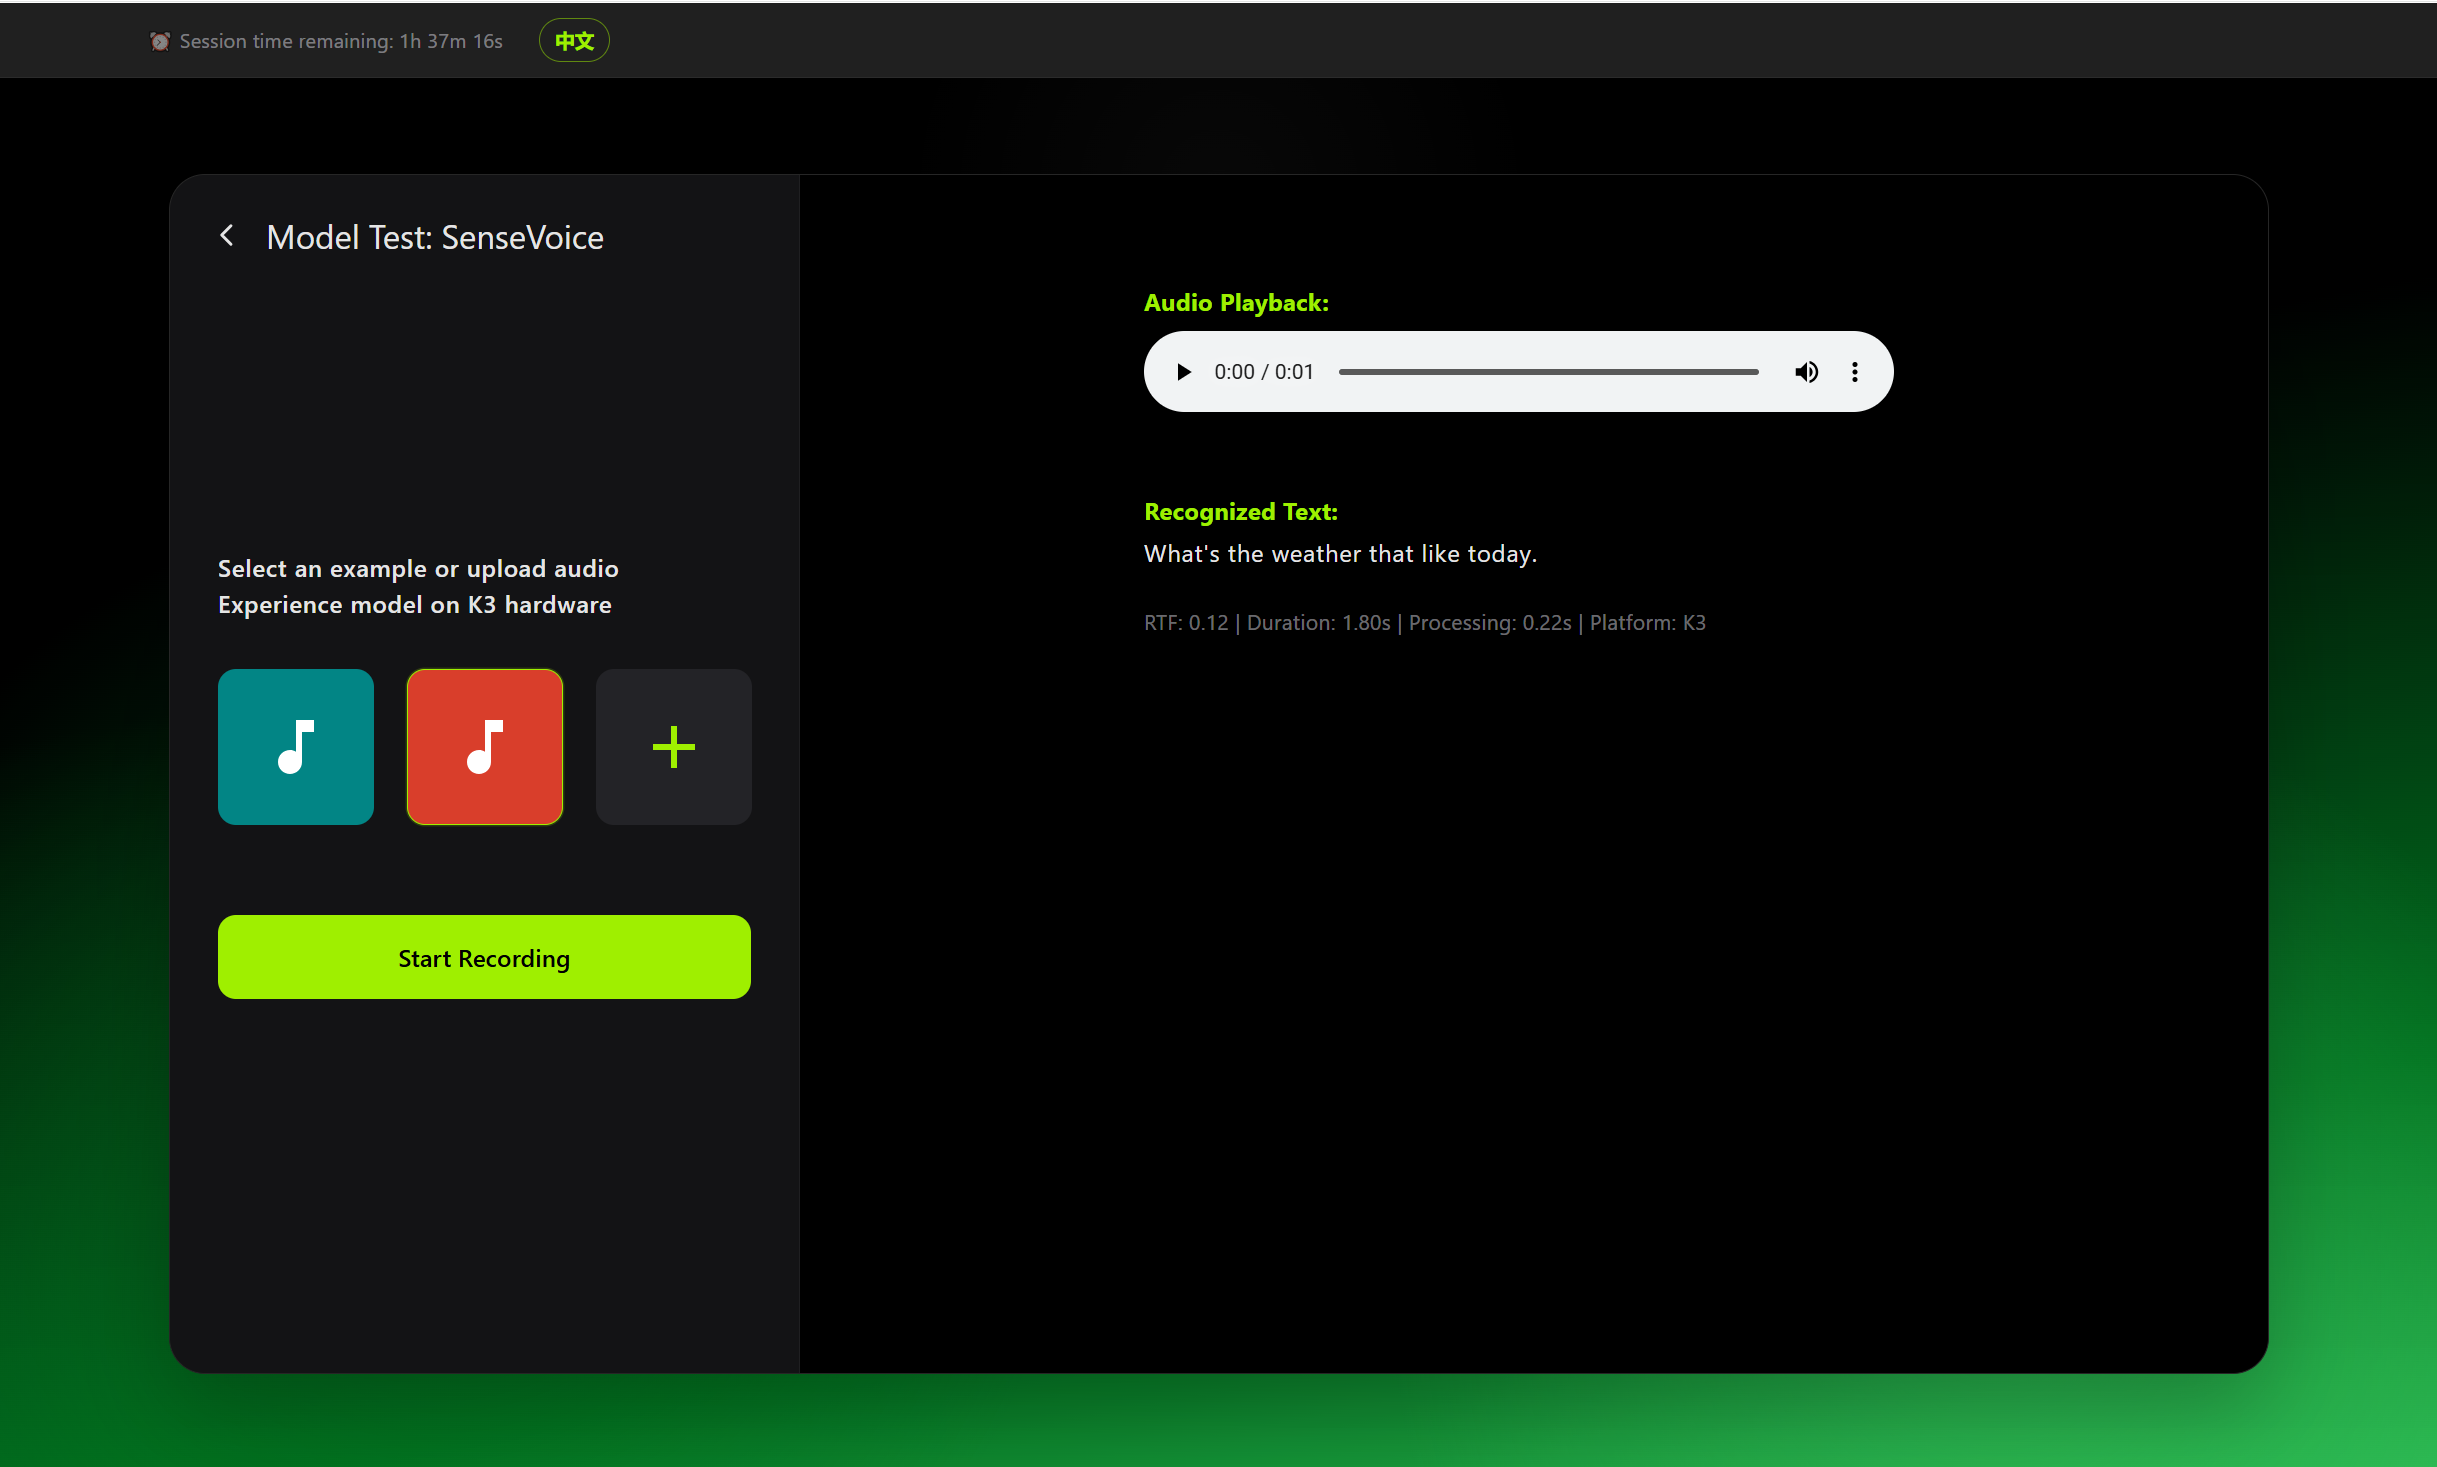
Find an ASR model (e.g., SenseVoice) and click Try Now.
-
Choose an input method:
-
Sample audio: Click a sample in the left panel to transcribe it immediately.
-
Upload audio: WAV format supported.
-
Live recording: Click Start Recording, speak, then click Stop Recording. Transcription runs automatically.
-
The result panel displays the transcribed text and processing time.
Speech Synthesis (TTS)
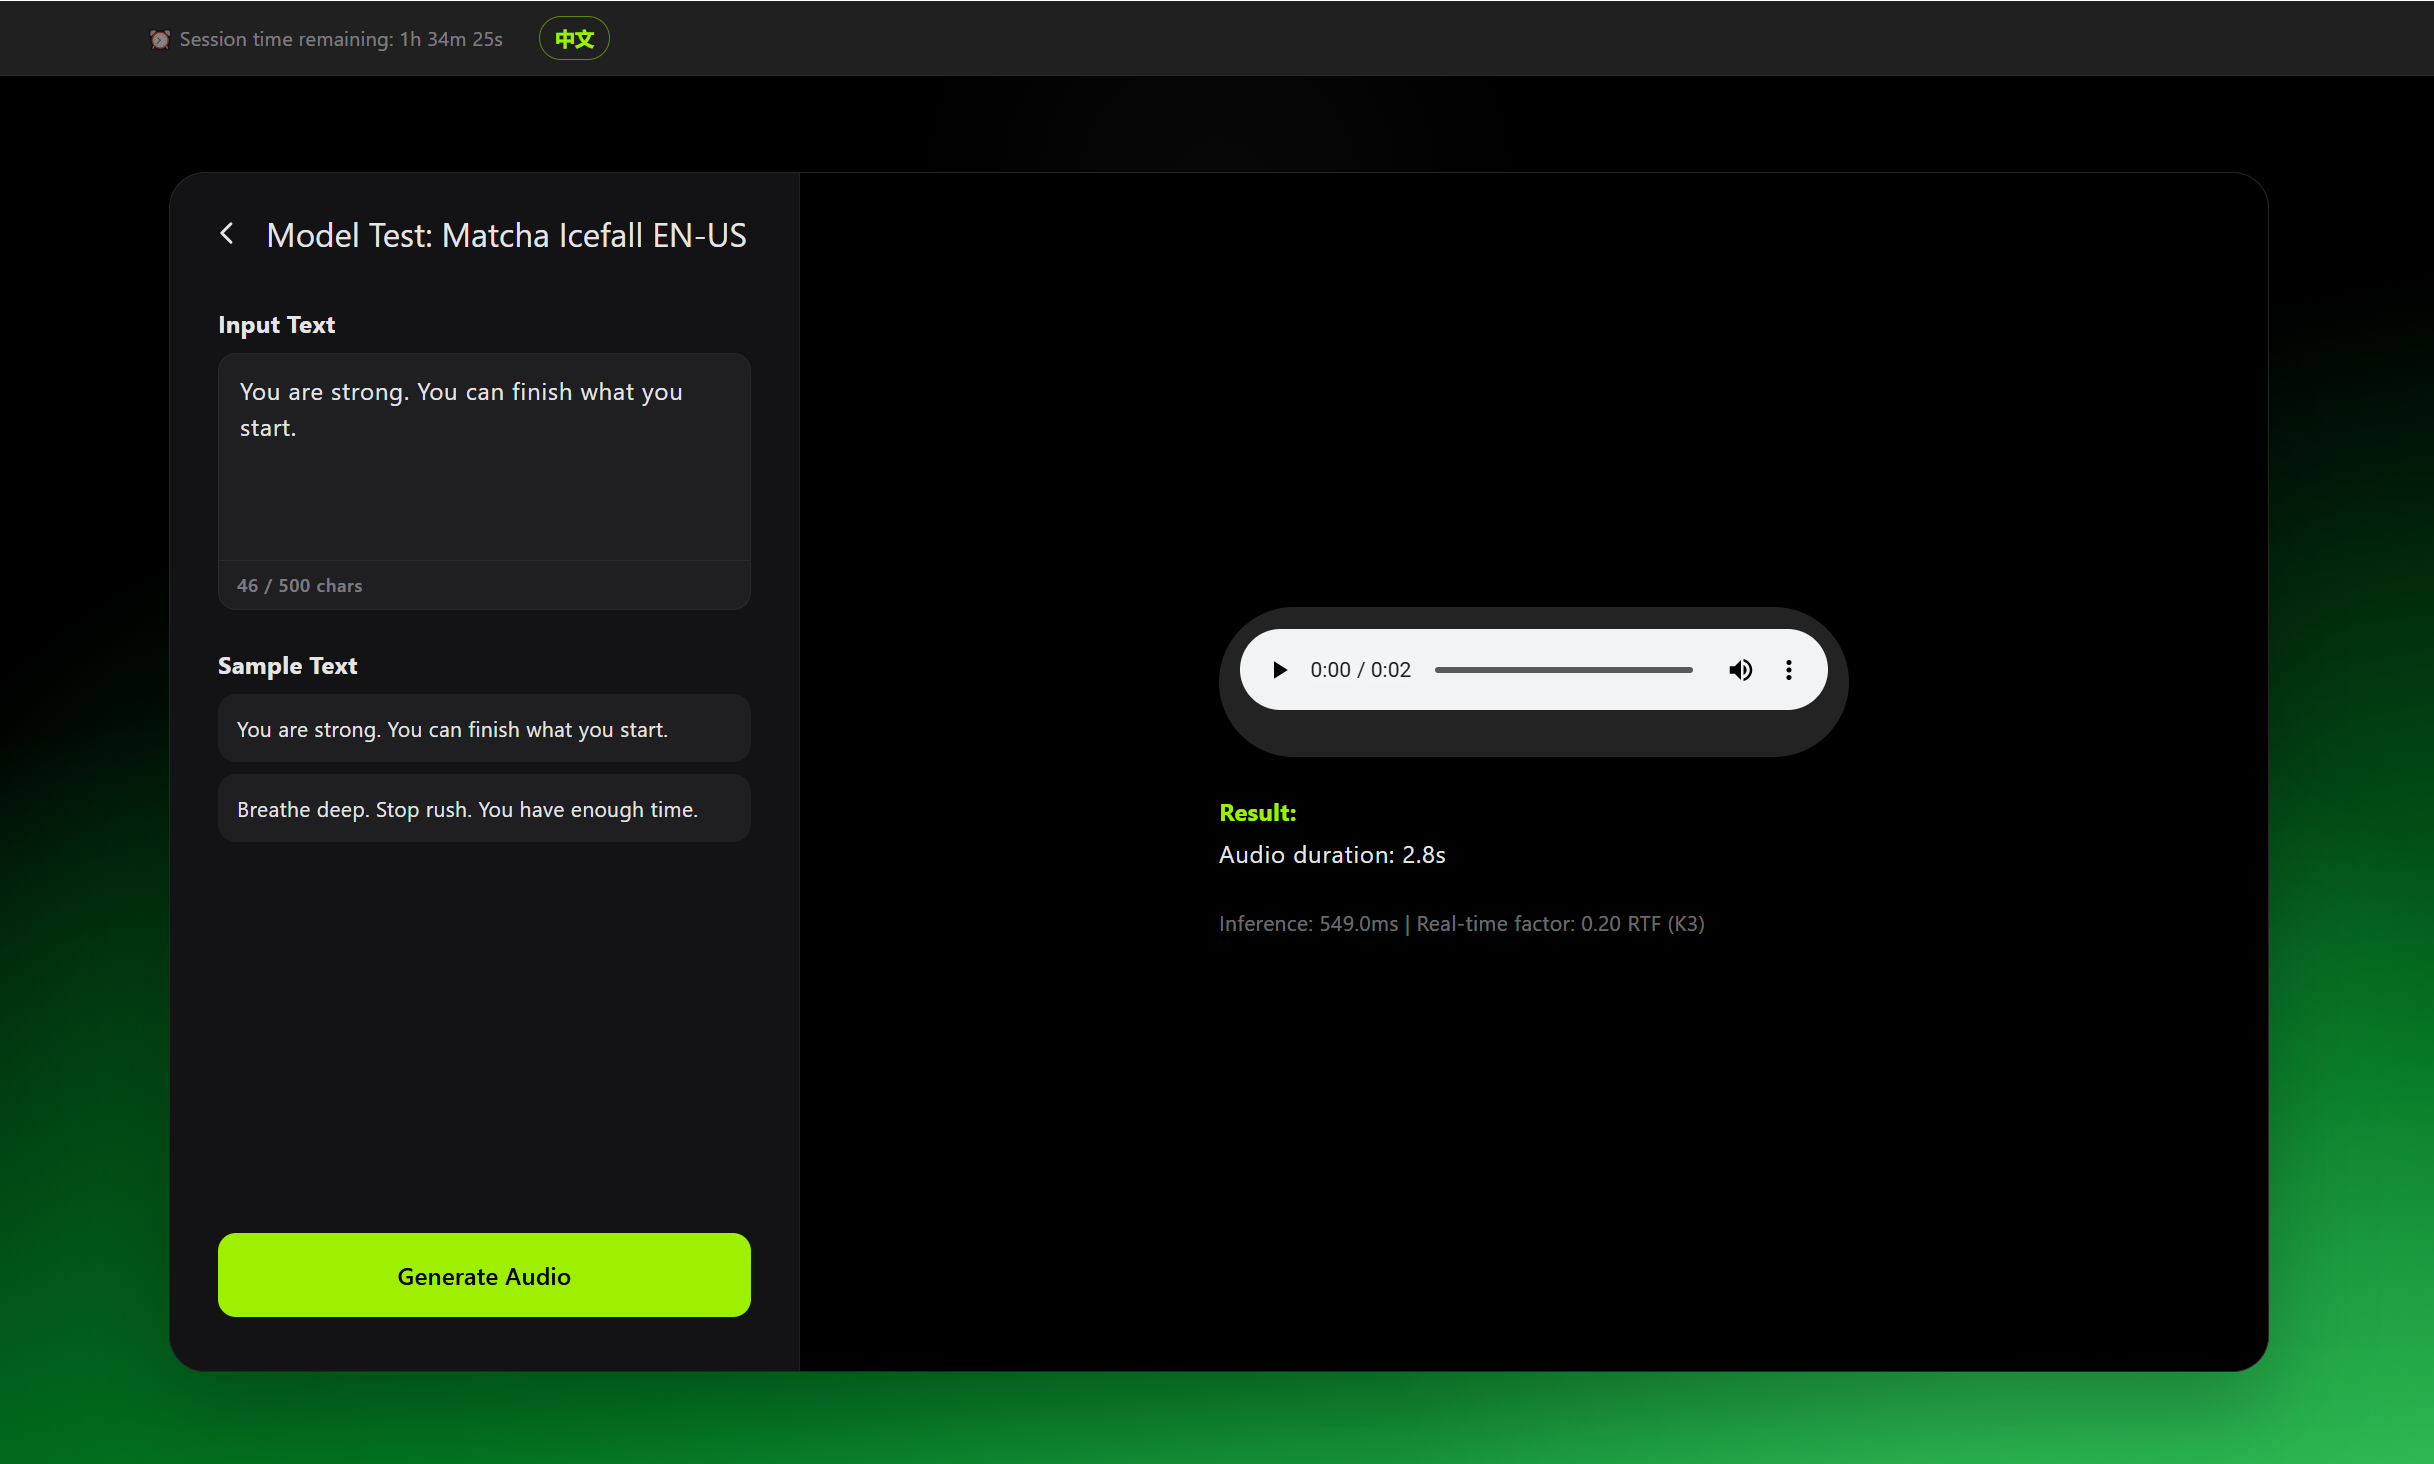
- Find a TTS model (e.g., Matcha Icefall EN-US, Matcha Icefall ZH-Baker, Matcha Icefall ZH-EN) and click Try Now.
- Enter text in the input box (up to 500 characters).
- Select Chinese or English input based on the model.
- Click Generate Audio. Playback starts automatically after synthesis completes.
Voice Activity Detection (VAD)
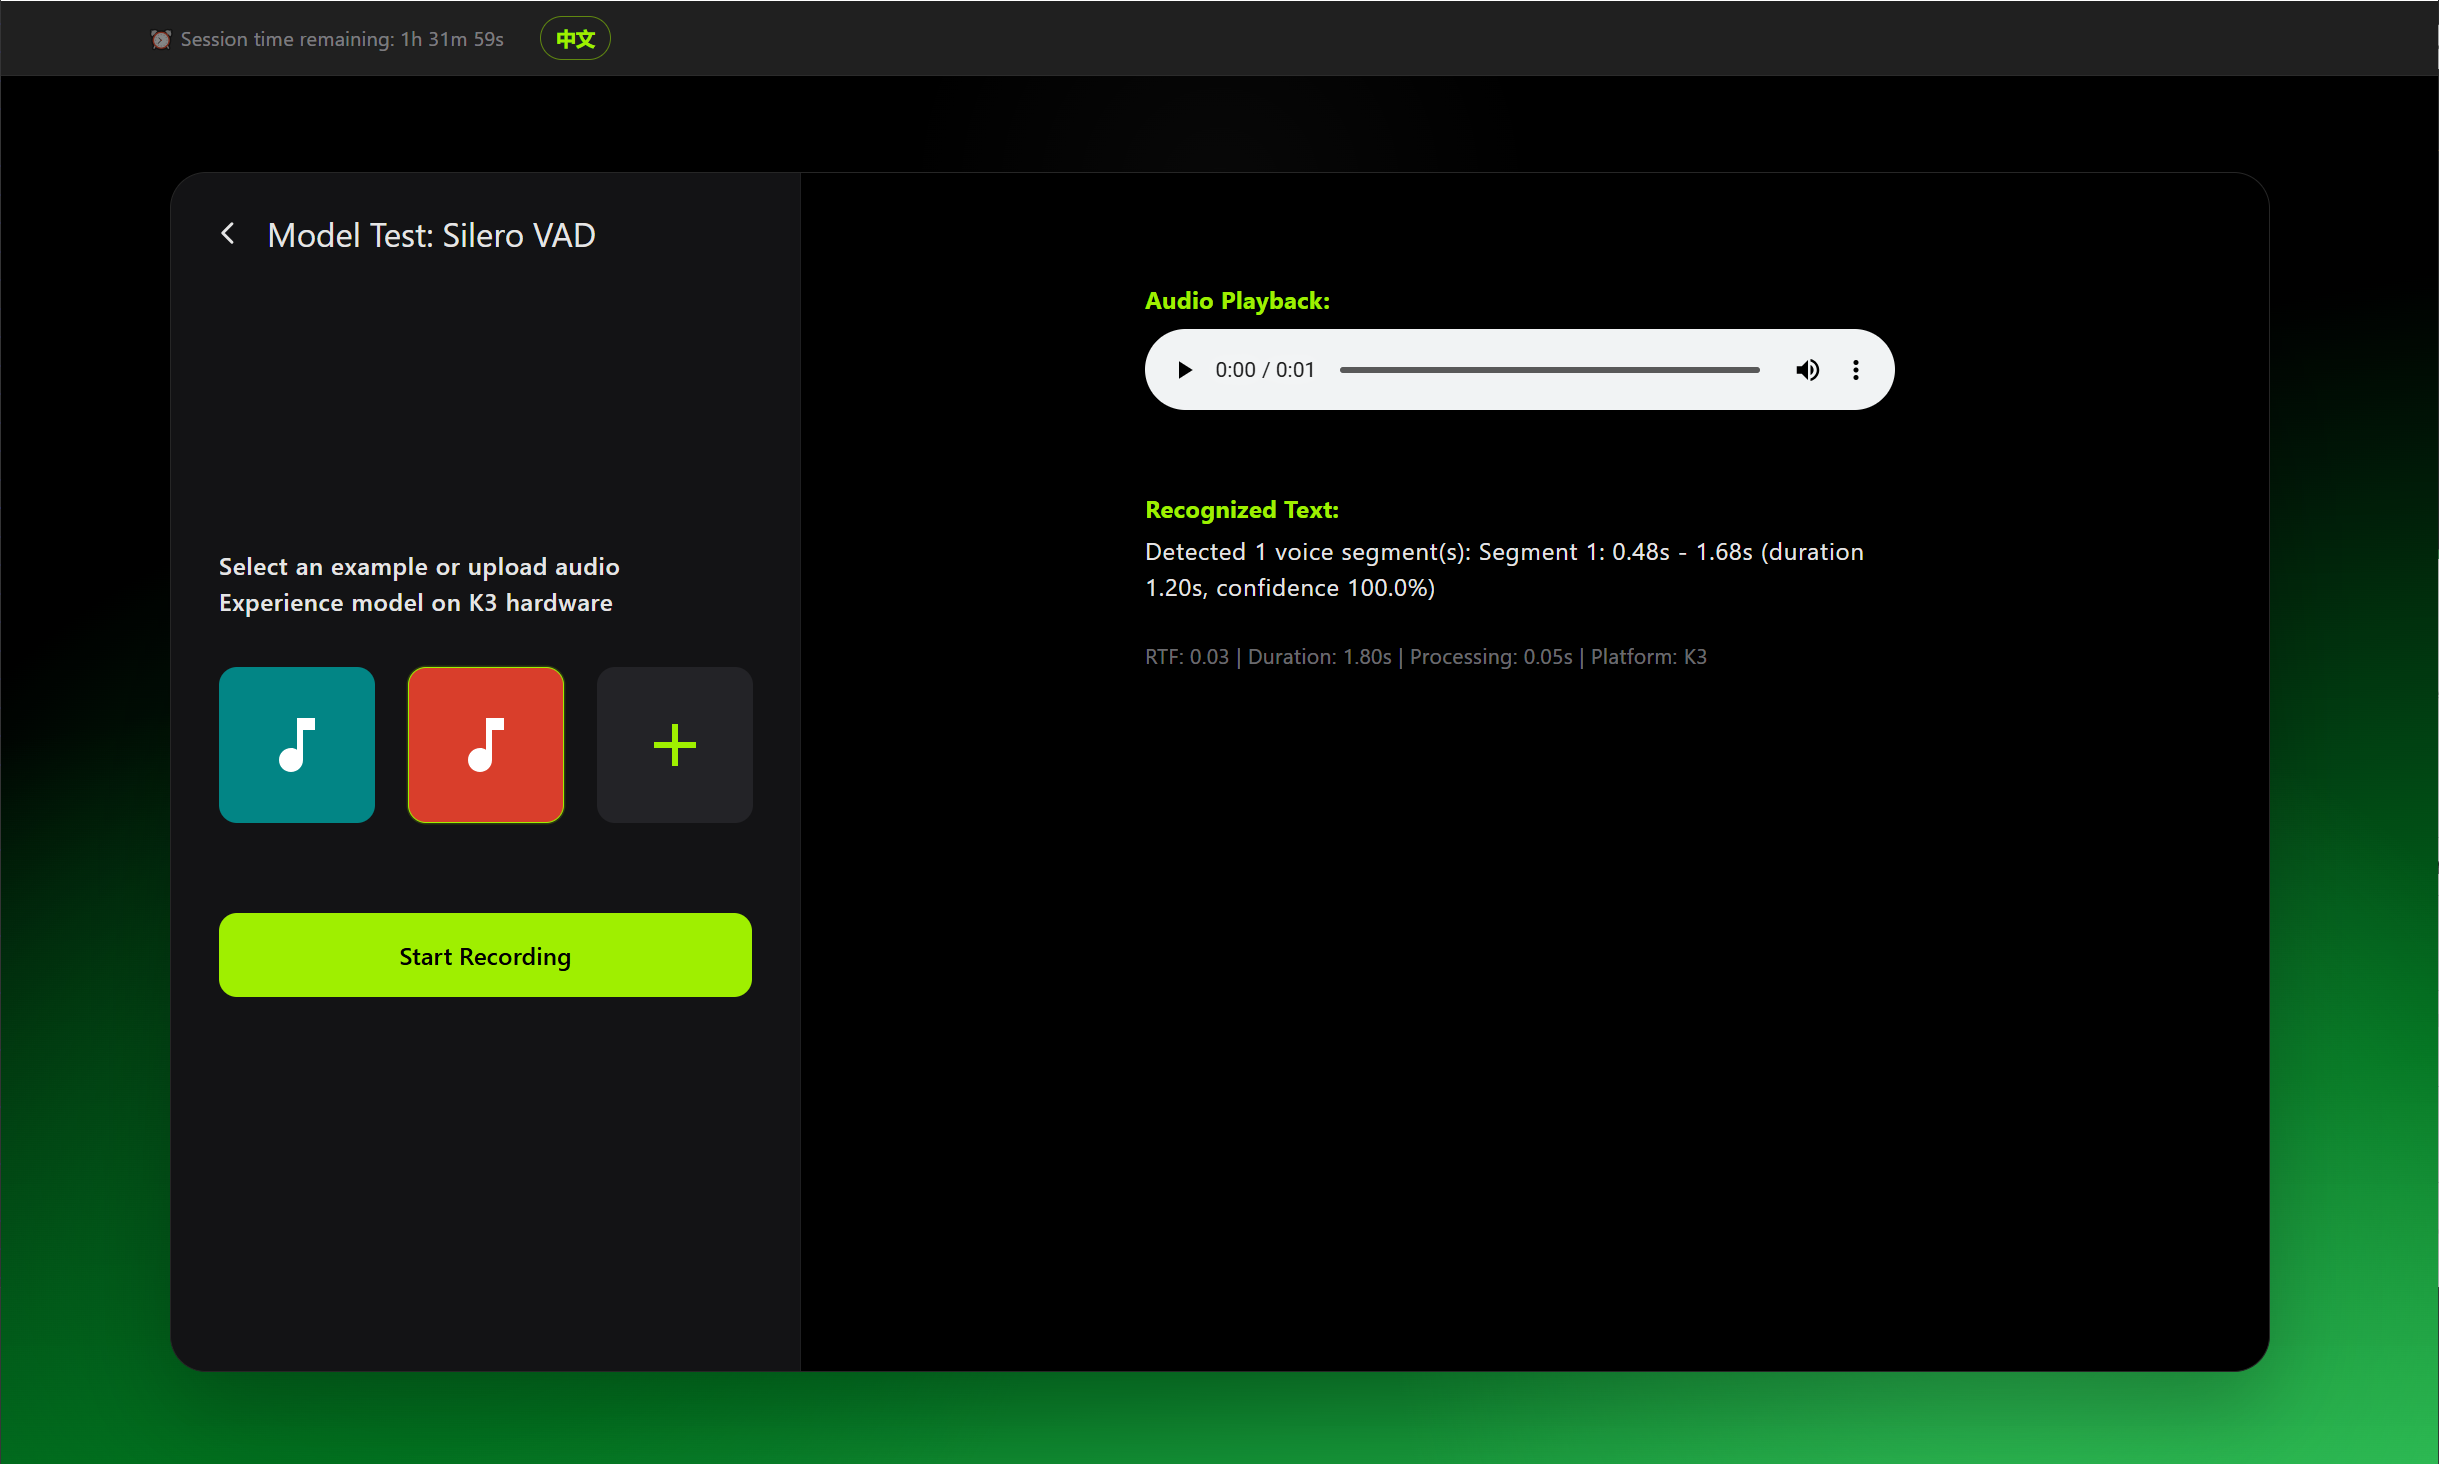
- Find the VAD model (Silero VAD) and click Try Now.
- Record audio or upload an audio file.
- Detection results are displayed visually with speech activity segments and time boundaries.
Model Performance DashboardView per-model performance metrics for K3 hardware at the bottom of the home page:
- Use the category tabs to filter Vision / LLM / Speech models.
- Metric definitions:
Metric
Full name
Description
PP128 (token/s)
Prompt Processing
Speed at which the model processes input prompts, measured over the first 128 tokens. Higher is better.
TG128 (token/s)
Token Generation
Speed at which the model generates output tokens, measured over subsequent 128 tokens. Higher is better.
RTF
Real-Time Factor
Ratio of processing time to audio duration. RTF < 1 means real-time capable. Lower is better.
FPS
Frames Per Second
Number of image frames processed per second by vision models. Higher is better.
Quantization
Quantization type
Model compression precision (e.g., Q4_0, Q8_0, INT8, FP16). Lower precision means smaller size and faster speed.
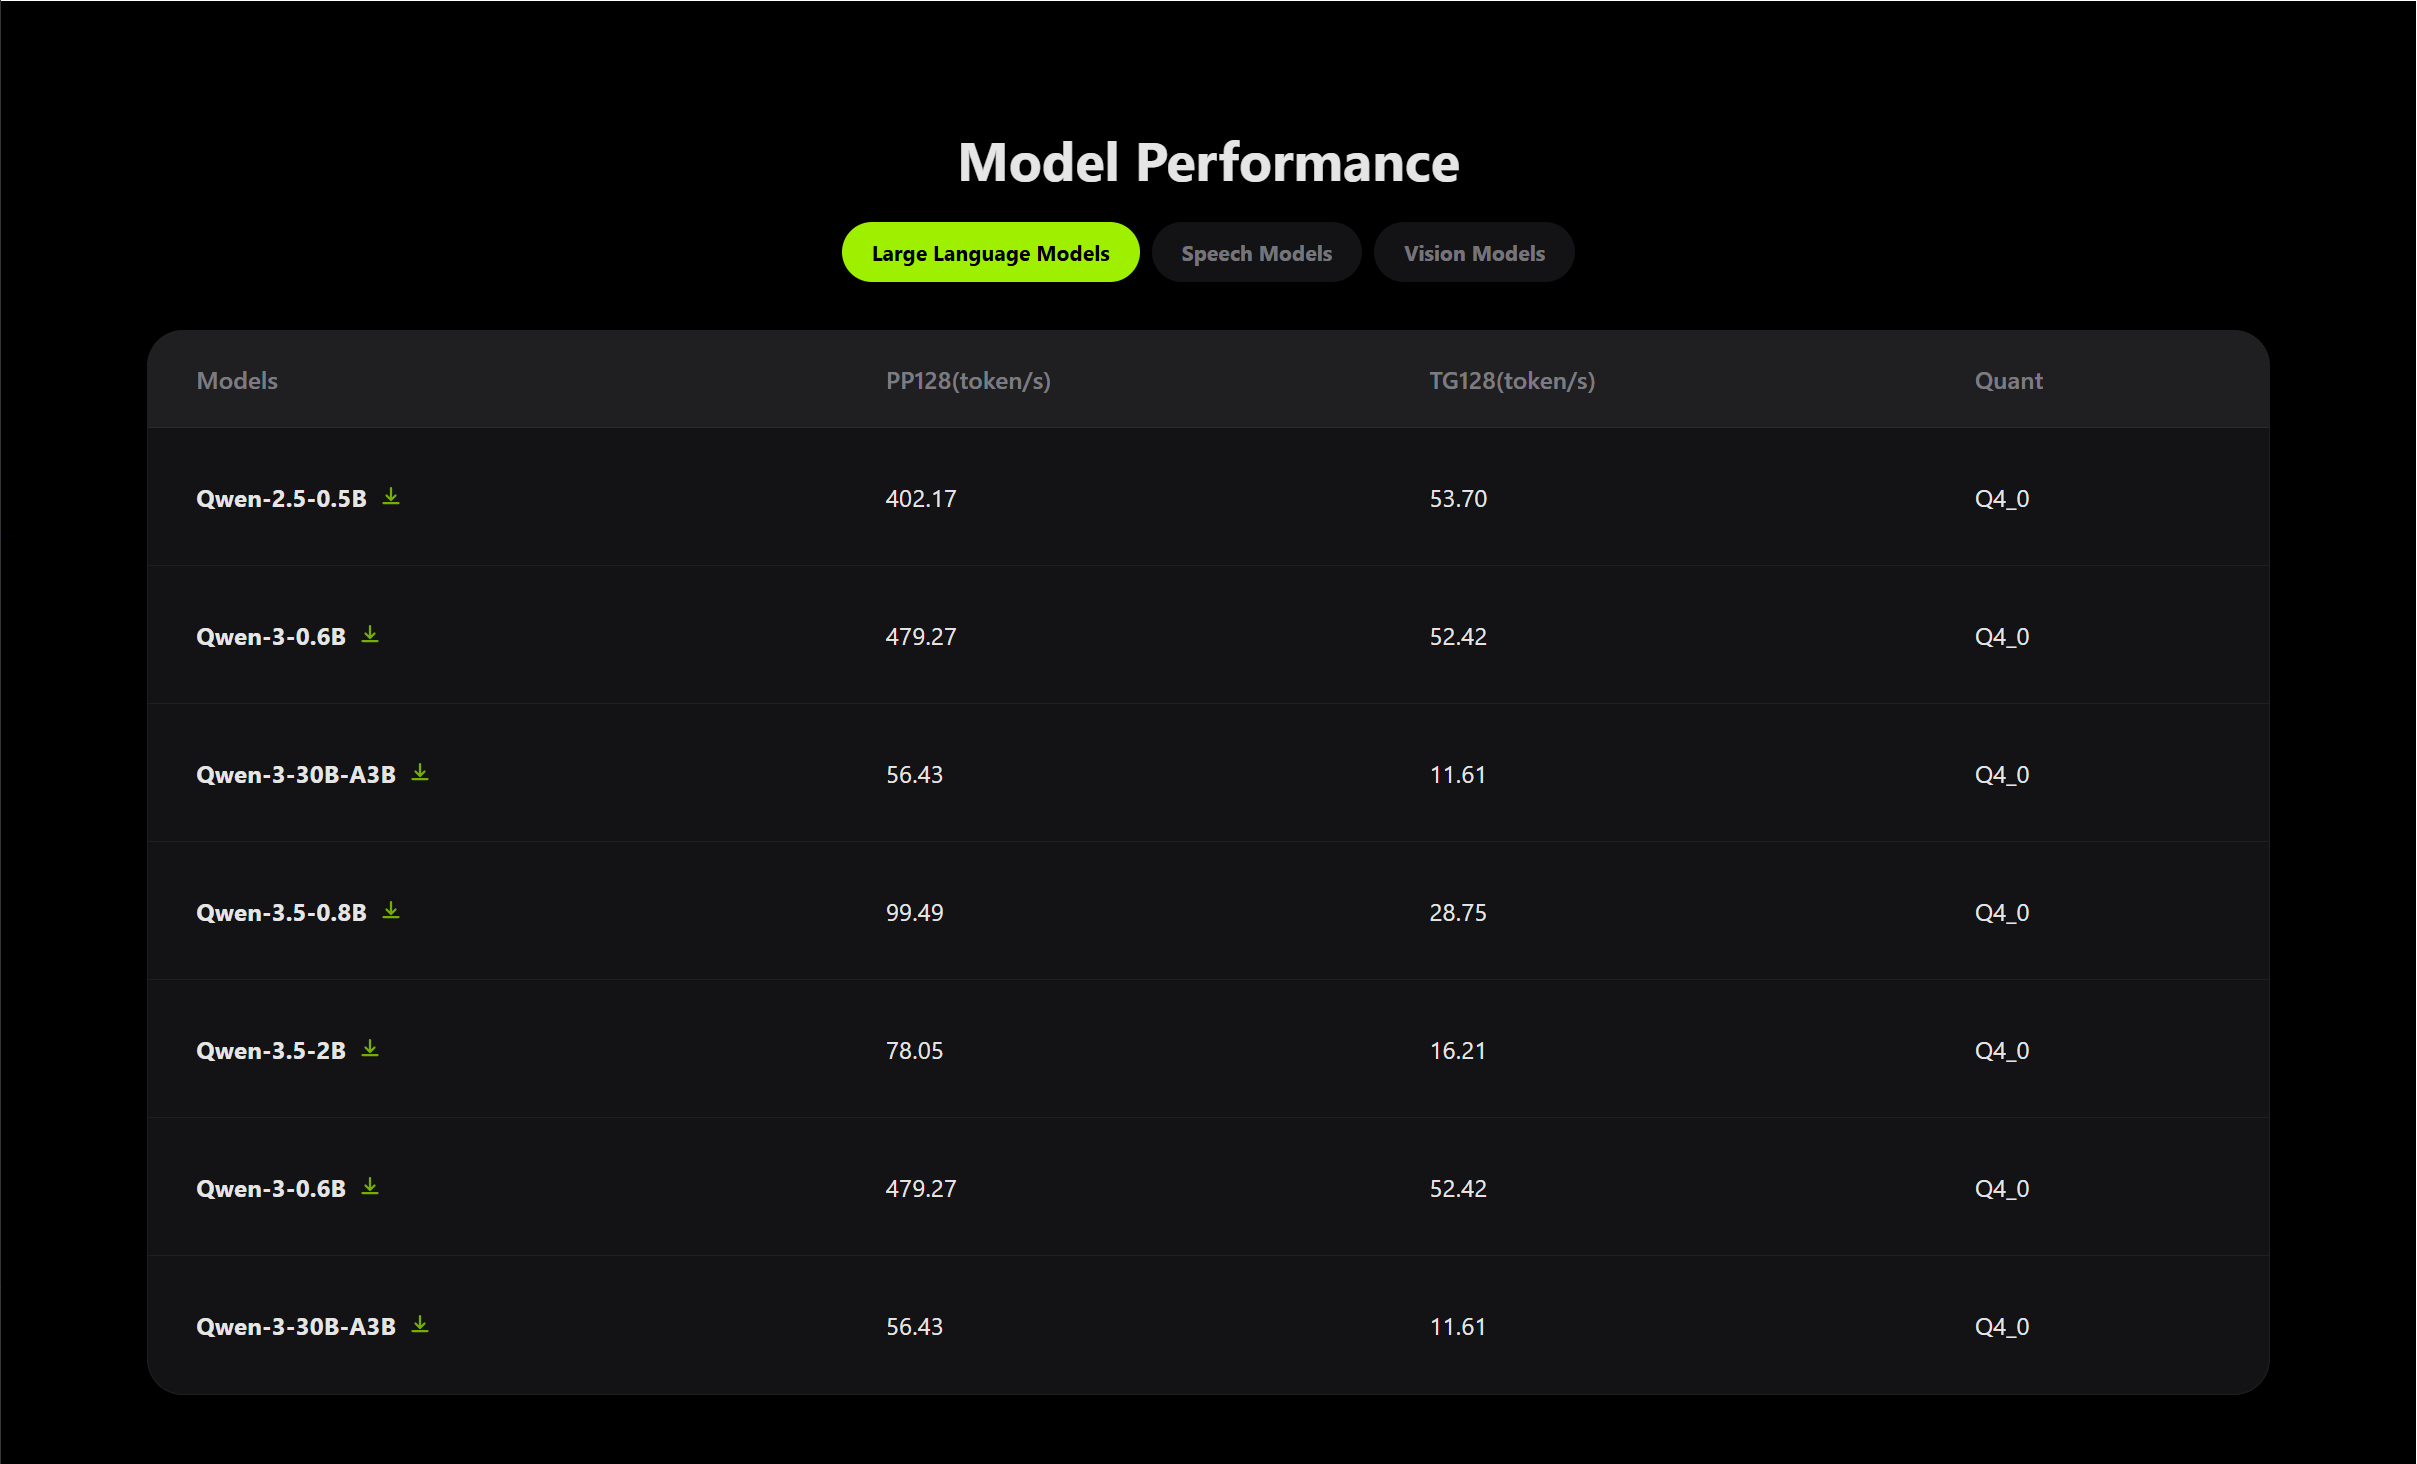
Models can also be downloaded from this view:
- Click the Download icon in the model row to start downloading.
- Files are saved to the browser’s default download directory.
Advanced Features
Auto-Start on BootToggle the Auto-Start on Boot switch in the top bar so AI Lab starts automatically with the system, making it always accessible to other devices on the local network.
Language SwitchClick the language button (EN / Chinese) in the top-right corner to switch the interface language.
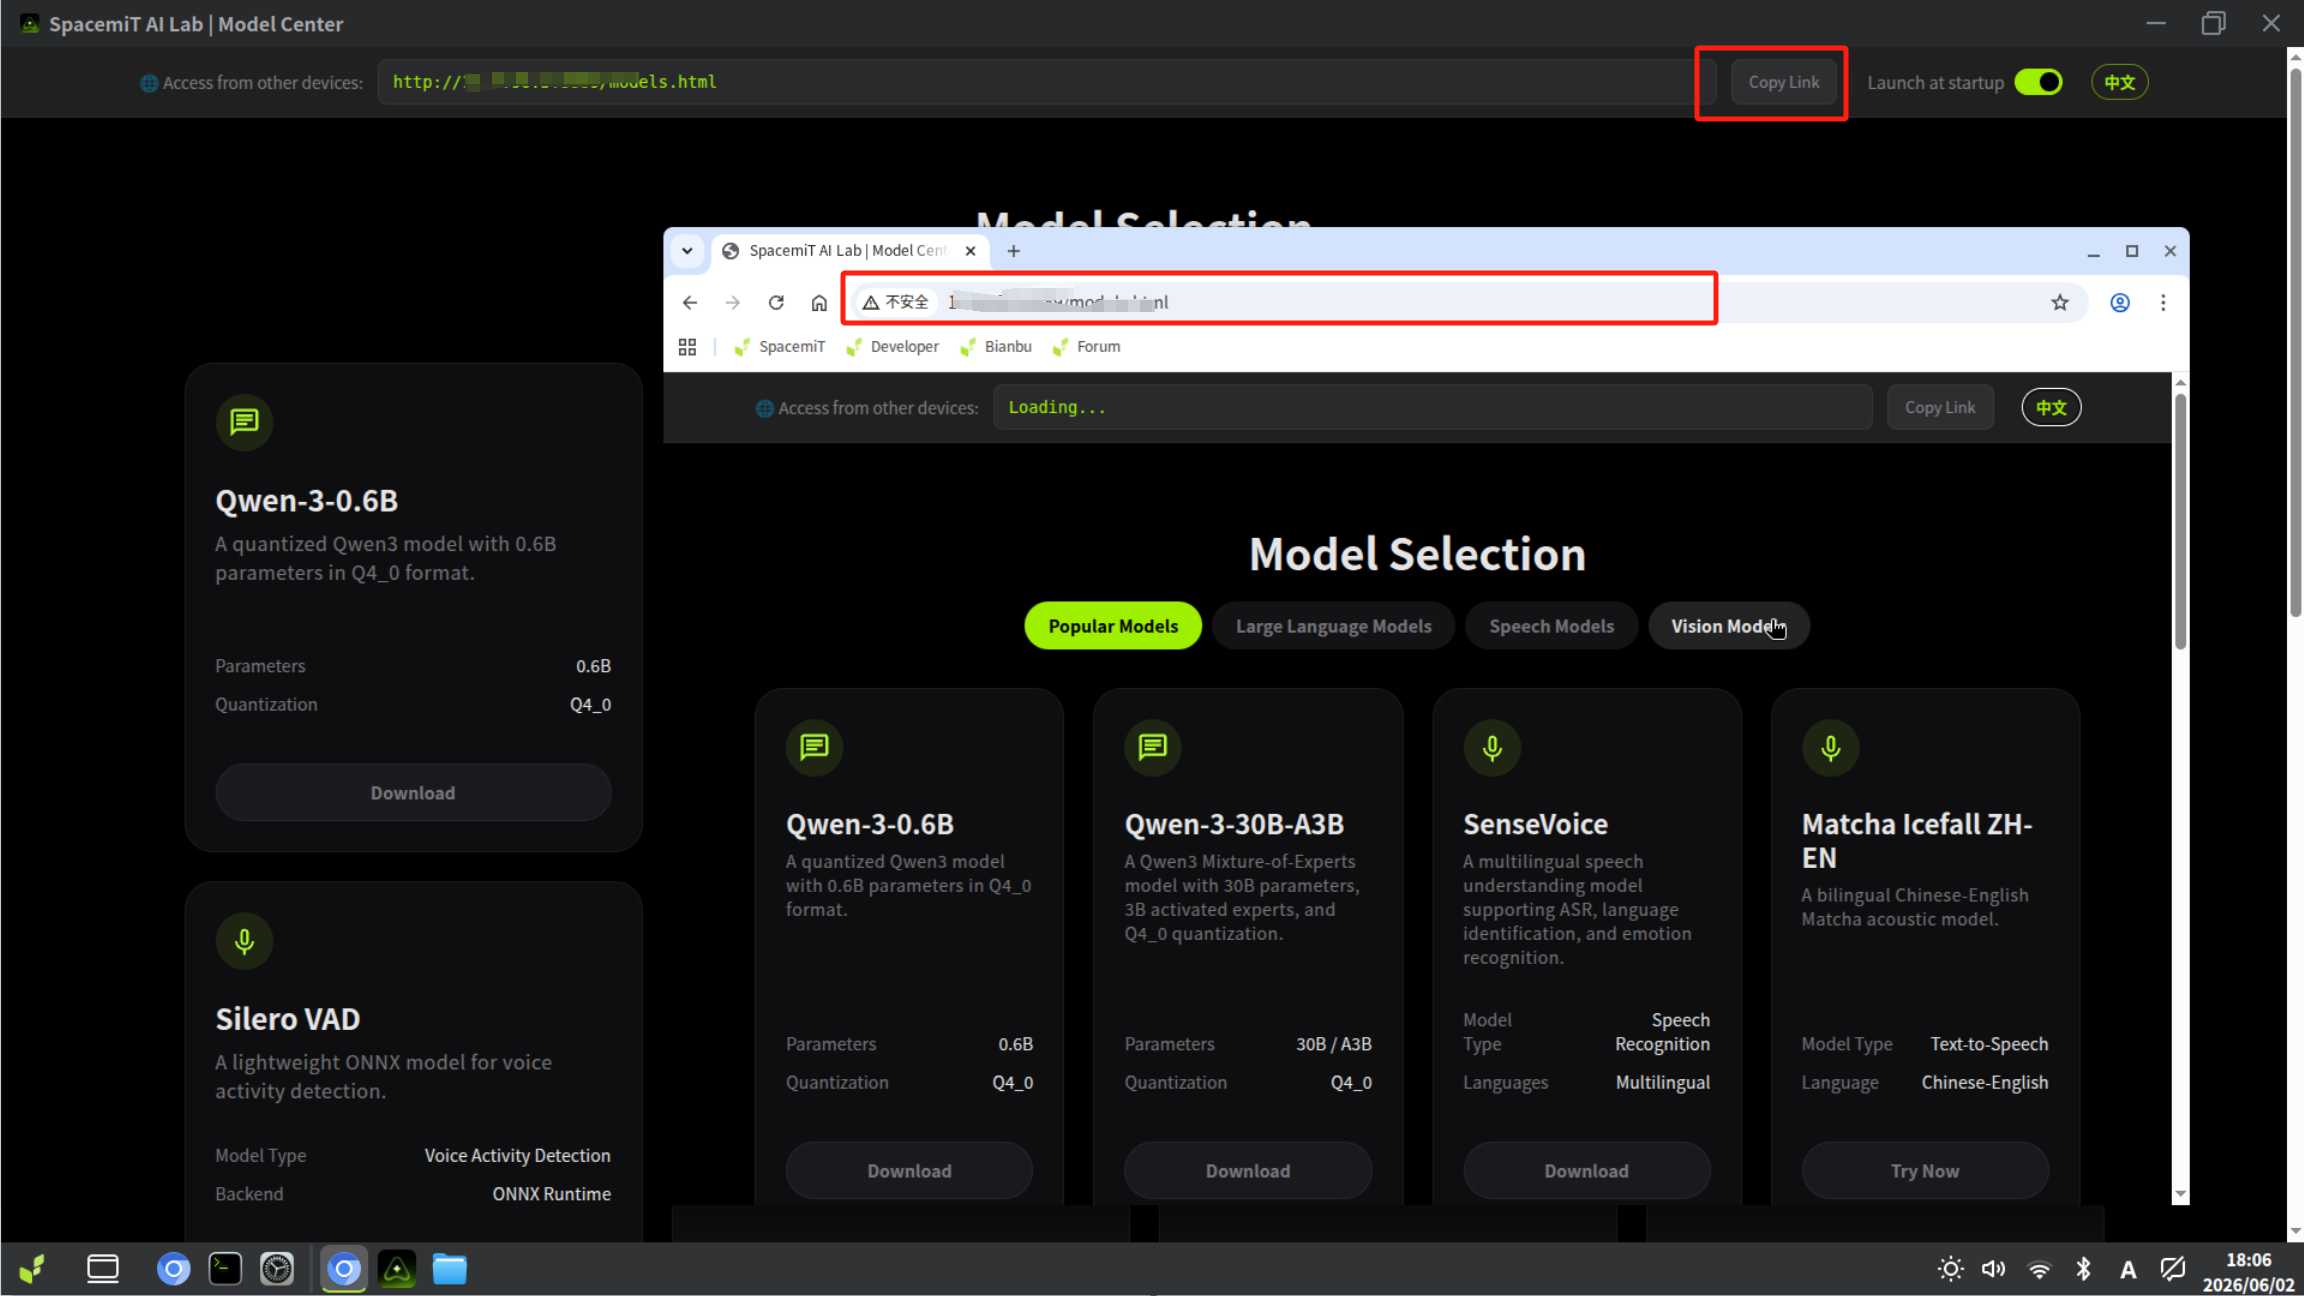
LAN SharingLAN sharing is enabled automatically when the app starts.
- Note the access URL shown at the top of the interface.
- Other devices on the same local network can open that URL in any browser — no installation required.
FAQ
App fails to start
# Check AI Gateway service status
systemctl status spacemit-ai-gateway

# Restart the service
sudo systemctl restart spacemit-ai-gateway

# Check for port conflicts
netstat -tulpn | grep 18790
Model download fails
- Verify the network connection is working.
- Check available disk space: df -h
- Remove unused model files and retry.
Inference is slow
- Use a smaller model variant (e.g., YOLOv8n instead of YOLOv8m).
- Close other resource-intensive applications.
- Run only one inference task at a time.
LAN sharing is not accessible from other devices
- Confirm both devices are on the same local network.
- Check that port 8889 is allowed through the firewall.
How do I view logs?
# Stream AI Gateway logs
journalctl -u spacemit-ai-gateway -f
How do I uninstall the app?
sudo apt remove spacemit-ailab spacemit-ai-gateway
# Optionally remove downloaded models
rm -rf ~/.cache/models/
Supported Models
Type
Representative models
Format
LLM
Qwen2.5 / Qwen3 / Qwen3.5 series
GGUF
Vision
YOLOv5/v8/v11 series, ResNet50
ONNX
ASR
SenseVoice, Qwen3-ASR
tar.gz
TTS
Matcha-TTS (Chinese / English)
tar.gz
VAD
Silero VAD
tar.gz
Support
- Official documentation: SpacemiT documentation
- Developer community: SpacemiT community
- Issue reporting: Submit via the community forum or GitLab Issues